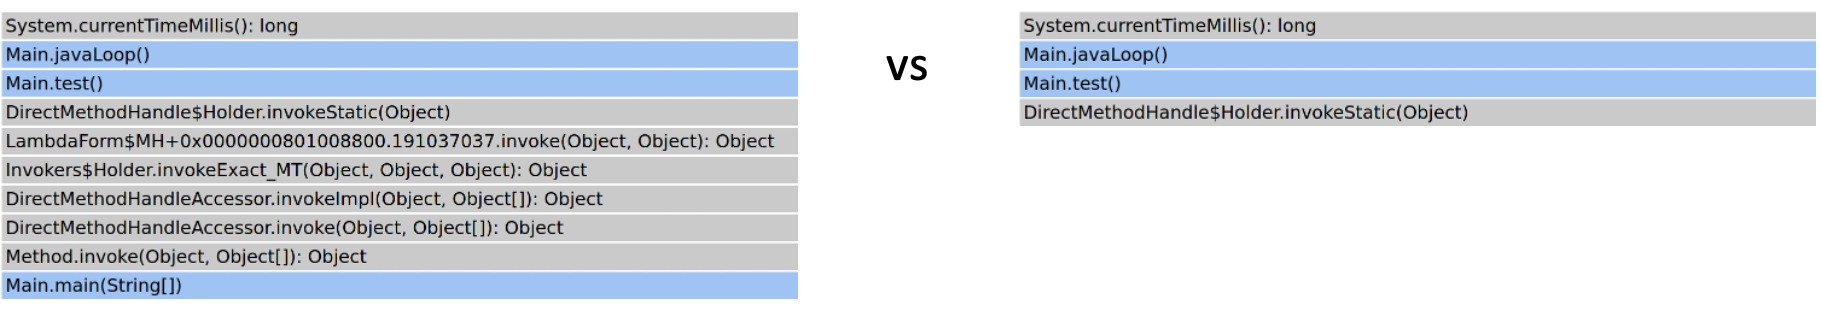
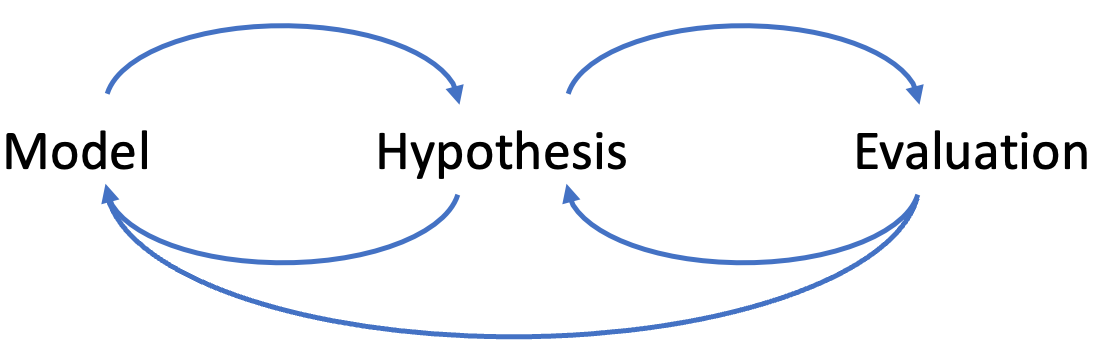
Understanding class loader hierarchies is essential when developing Java agents, especially if these agents are instrumenting code. In my Instrumenting Java Code to Find and Handle Unused Classes post, I instrumented all classes with an agent and used a Store class in this newly added code:
A challenge here is that all instrumented classes will use the Store. We, therefore, have to put the store onto the bootstrap classpath, making it visible to all classes.
Class loaders are responsible for (possibly dynamically) loading classes, and they form a hierarchy:
A class loader is an object that is responsible for loading classes. The class ClassLoader is an abstract class. Given the binary name of a class, a class loader should attempt to locate or generate data that constitutes a definition for the class. A typical strategy is to transform the name into a file name and then read a “class file” of that name from a file system.
[…]
The ClassLoader class uses a delegation model to search for classes and resources. Each instance of ClassLoader has an associated parent class loader. When requested to find a class or resource, a ClassLoader instance will usually delegate the search for the class or resource to its parent class loader before attempting to find the class or resource itself.
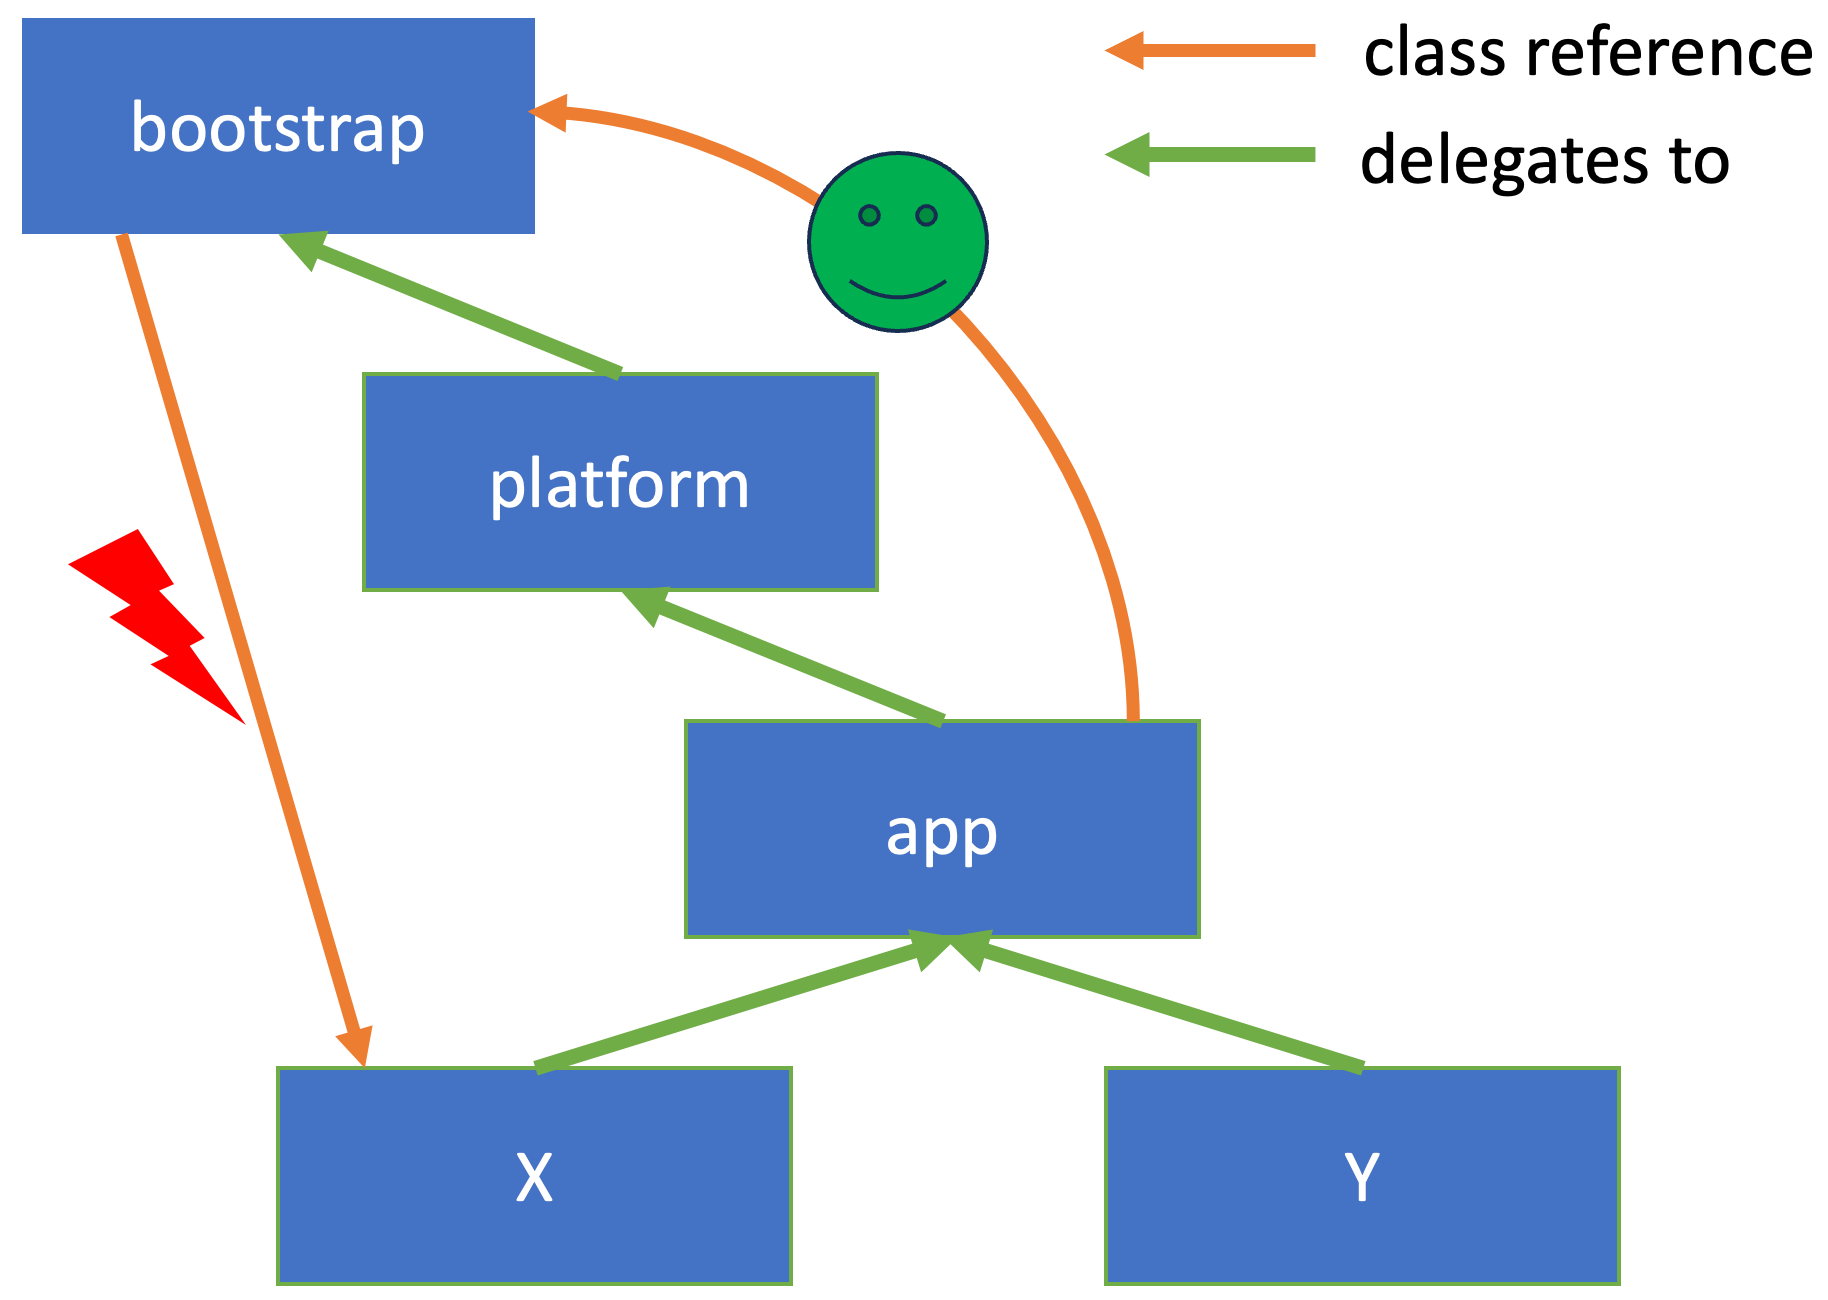
A typical Java application has a bootstrap class loader (internal JDK classes and the ClassLoader class itself, implemented in C++ code), a platform classloader (all other JDK classes), and an application/system class loader (application classes):
Bootstrap class loader. It is the virtual machine’s built-in class loader, typically represented as null, and does not have a parent.
Platform class loader. The platform class loader is responsible for loading the platform classes. Platform classes include Java SE platform APIs, their implementation classes and JDK-specific run-time classes that are defined by the platform class loader or its ancestors. The platform class loader can be used as the parent of a ClassLoader instance. […]
System class loader. It is also known as application class loader and is distinct from the platform class loader. The system class loader is typically used to define classes on the application class path, module path, and JDK-specific tools. The platform class loader is the parent or an ancestor of the system class loader, so the system class loader can load platform classes by delegating to its parent.
An application might create more class loaders to load classes, e.g., from JARs or do some access control; these classes typically have the application class loader as their parent.
Classes loaded by the application class loader (or children of it) can reference JDK classes but not vice versa. This leads to the problem mentioned before. We can mitigate this by putting all classes that our instrumentation-generated code uses into a runtime JAR which we then “put” on the bootstrap class path.
But we don’t put it there but instead tell the bootstrap class loader to also look into our runtime JAR when looking for a class. We do this by using the method void appendToBootstrapClassLoaderSearch(JarFile jarfile) of the Instrumentation class:
Specifies a JAR file with instrumentation classes to be defined by the bootstrap class loader.
When the virtual machine’s built-in class loader, known as the “bootstrap class loader”, unsuccessfully searches for a class, the entries in the JAR file will be searched as well.
This method may be used multiple times to add multiple JAR files to be searched in the order that this method was invoked.
But the documentation also tells us that you can create a giant mess when you aren’t careful, including only the minimal number of required classes in the added JAR:
The agent should take care to ensure that the JAR does not contain any classes or resources other than those to be defined by the bootstrap class loader for the purpose of instrumentation. Failure to observe this warning could result in unexpected behavior that is difficult to diagnose. For example, suppose there is a loader L, and L’s parent for delegation is the bootstrap class loader. Furthermore, a method in class C, a class defined by L, makes reference to a non-public accessor class C$1. If the JAR file contains a class C$1 then the delegation to the bootstrap class loader will cause C$1 to be defined by the bootstrap class loader. In this example an IllegalAccessError will be thrown that may cause the application to fail. One approach to avoiding these types of issues, is to use a unique package name for the instrumentation classes.
You have to append the classes to the search path before (!) the first reference of the classes, as a class that cannot be resolved when first referenced will never be adequately resolved.
More information on class loaders can be found in the Baeldung article Class Loaders in Java.
How to get the class loader hierarchy of your project
I wanted to know the class loader hierarchy for my own projects, so of course, I wrote an agent for it: The ClassLoader Hierarchy Agent prints the class loader hierarchy at agent load time, the JVM shutdown, and in regular intervals.
Its usage is quite simple. Just attach it to a JVM or add it at startup:
Usage: java -javaagent:classloader-hierarchy-agent.jar[=maxPackages=10,everyNSeconds=0] <main class>
  maxPackages: maximum number of packages to print per classloader
  every: print the hierarchy every N seconds (0 to disable)
For the finagle-httprenaissance benchmark, the agent, for example, prints the following when the benchmark is in full swing:
The root node is the bootstrap class loader. For every class loader, it gives us a thread that uses it as its primary class loader, a short list of packages associated with the class loader, and its child class loaders.
Class loaders can have names, but sadly not many class loader creators use this feature, which turns understanding the individual class loader hierarchies into a guessing game. This is especially the case for Spring based applications like the Spring PetClinic:
Feel free to try this agent on your applications; maybe you gain some new insights.
Conclusion
Understanding class loader hierarchies helps to understand subtle problems in writing instrumenting agents. Knowing how to write small agents can empower you to write simple tools to understand the properties of your application.
I hope this blog post helped you to understand class loader hierarchies and agents a little bit better. I’m writing it in a lovely park in Milan:
In my last blog post, I hinted Using Async-Profiler and Jattach Programmatically with AP-Loader, that I’m currently working on a test library for writing better profiling API tests. The library is still work-in-progress, but it already allows you to write profiling API tests in plain Java:
private int innerASGCT2() {
    new Tracer().runASGCT().assertTrue(
        Frame.hasMethod(0, "innerASGCT2", "()I"),
        Frame.hasMethod(1, "testRunASGCT2"));
    return 0;
}

@Test
public void testRunASGCT2() {
    innerASGCT2();
}
This test case checks that calling AsyncGetCallTrace gives the correct result in this specific example. The test library allows you to write tests comparing the returns of multiple GetStackTrace, AsyncGetCallTrace, and AsyncGetStackTrace invocations in different modes and settings. The library can be found as trace-tester on GitHub; I aim to bring it into the OpenJDK later with my JEP.
Writing small test cases this way is great, but it would be even better if we could force specific methods to be compiled, interpreted, or inlined so that we can test different scenarios. The proposed AsyncGetStackTrace will return the compilation level directly for every frame, so it is necessary to check the correctness of the level too.
Consider reading my Validating Java Profiling APIs post to get a different angle on profiling API testing.
Introduction
Before I start with discussing the ways you can force methods to be compiled, interpreted, or inlined, I’ll have to clarify that:
The following only works with the HotSpot tired JIT compiler and not other JVM’s like OpenJ9 (see issue #11272)
It should only be used for testing. I would refrain from using it anywhere near production, even if you know that specific methods should be compiled. Use a tool like JITWatch by Chris Newland to check whether the JVM doesn’t make the correct decisions automatically: Ask your fellow JVM expert how to deal with this.
I’m not an expert in the APIs I’m showing you, nor in tiered compilation, so be aware that I might be missing something, but I’m happy for any suggestions and corrections.
There are four different compilation levels, but I’m subsuming all C1 variants under the C1 label because some of my used techniques only work on the C1/C2/inlined level. You can read more on tiered compilation in articles like Tiered Compilation in JVM on Baeldung.
Now that I finished the obligatory disclaimer: What are the stages in the life of a method with a tiered JIT?
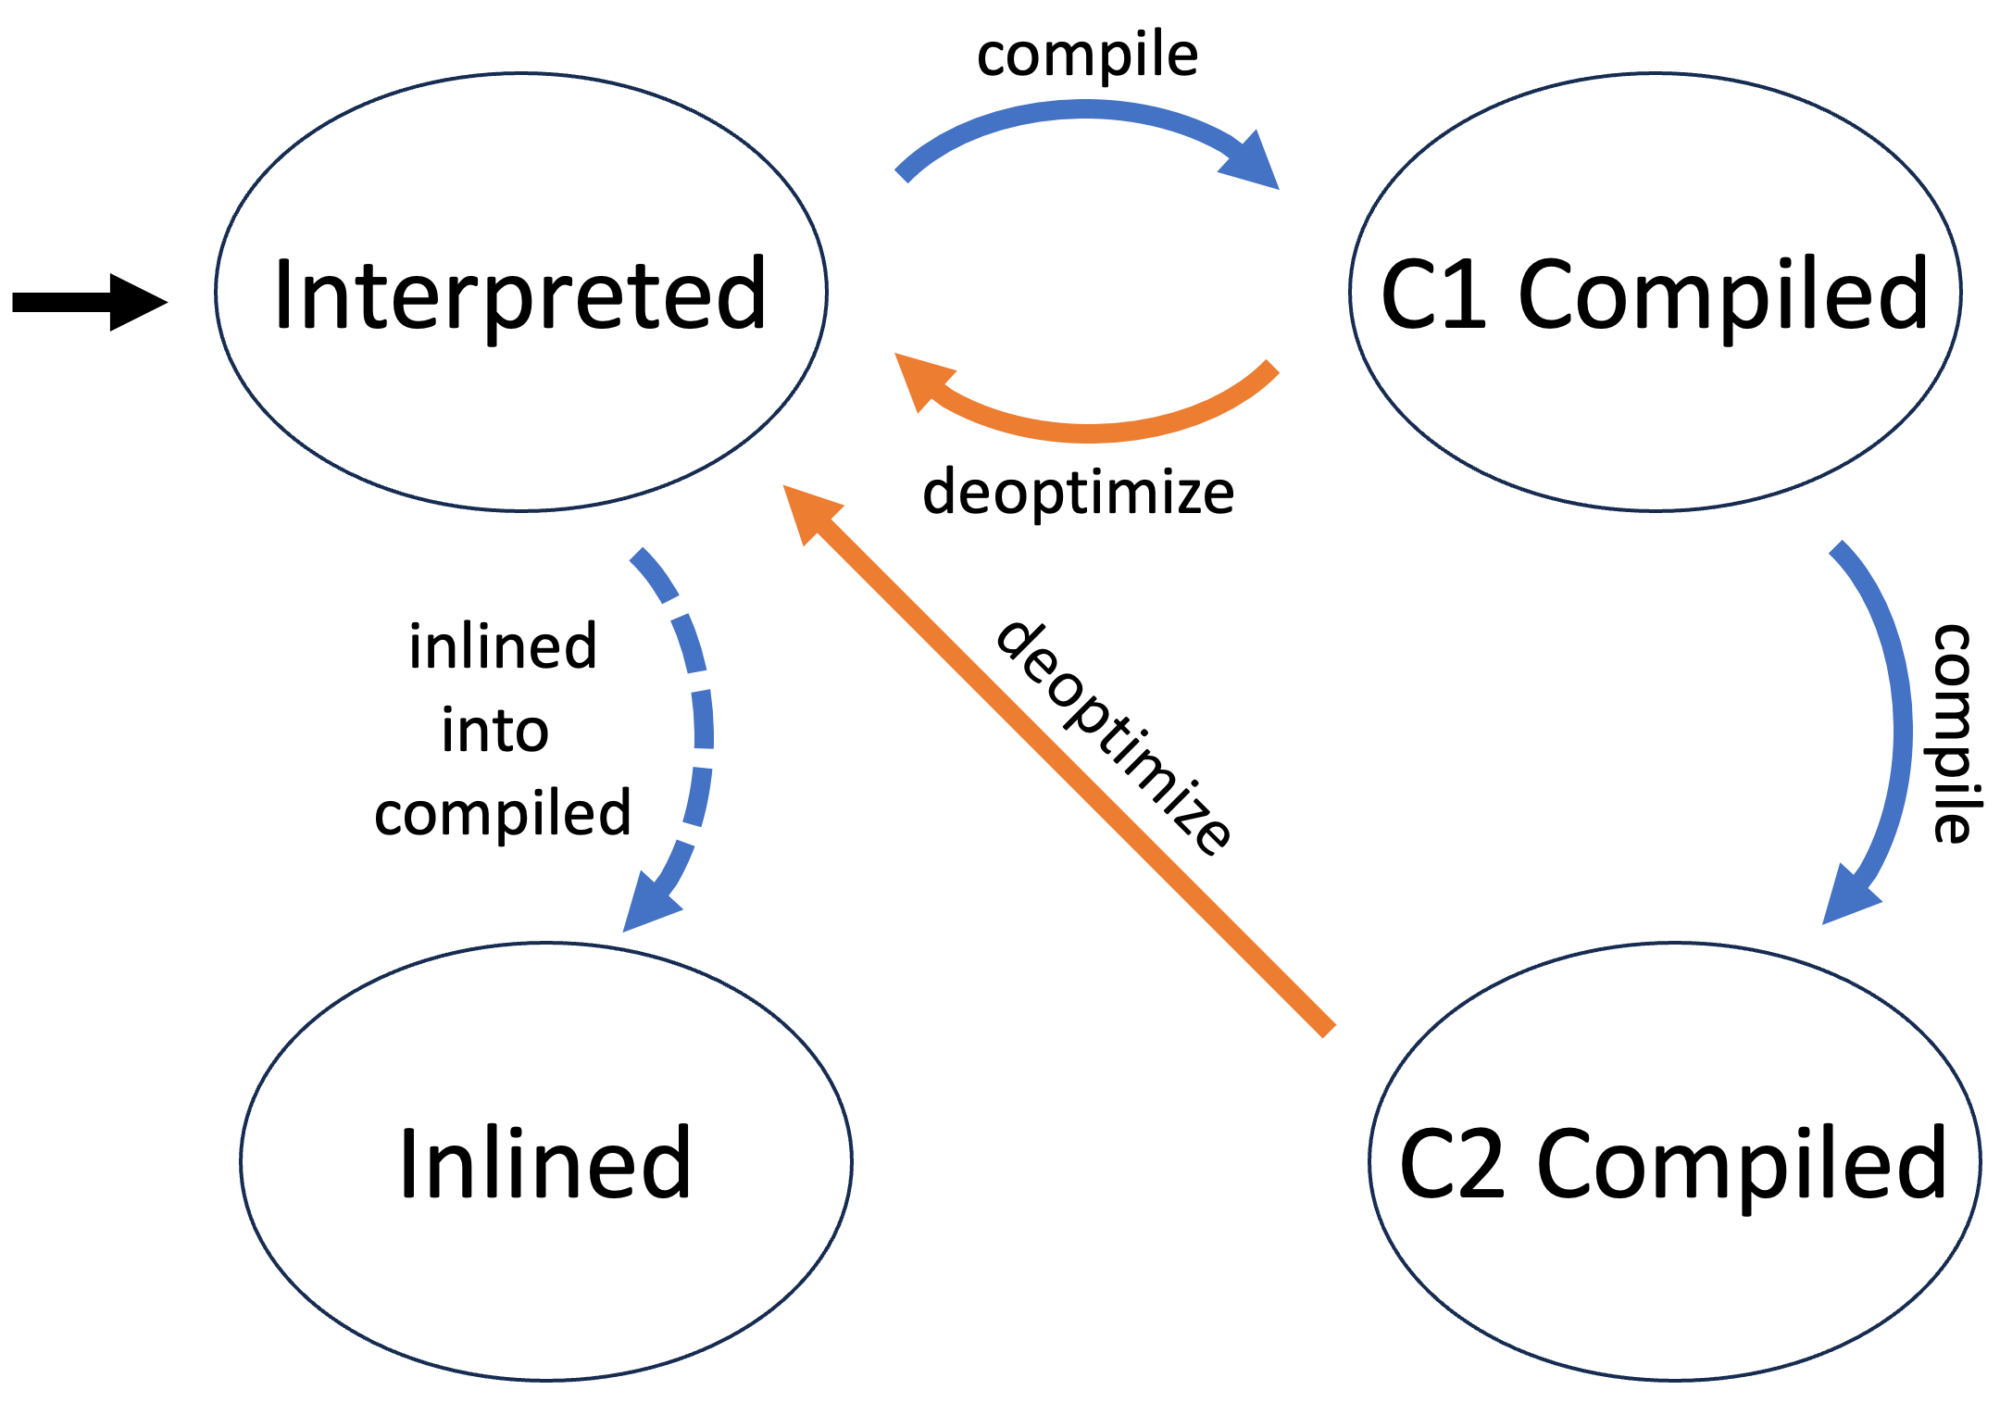
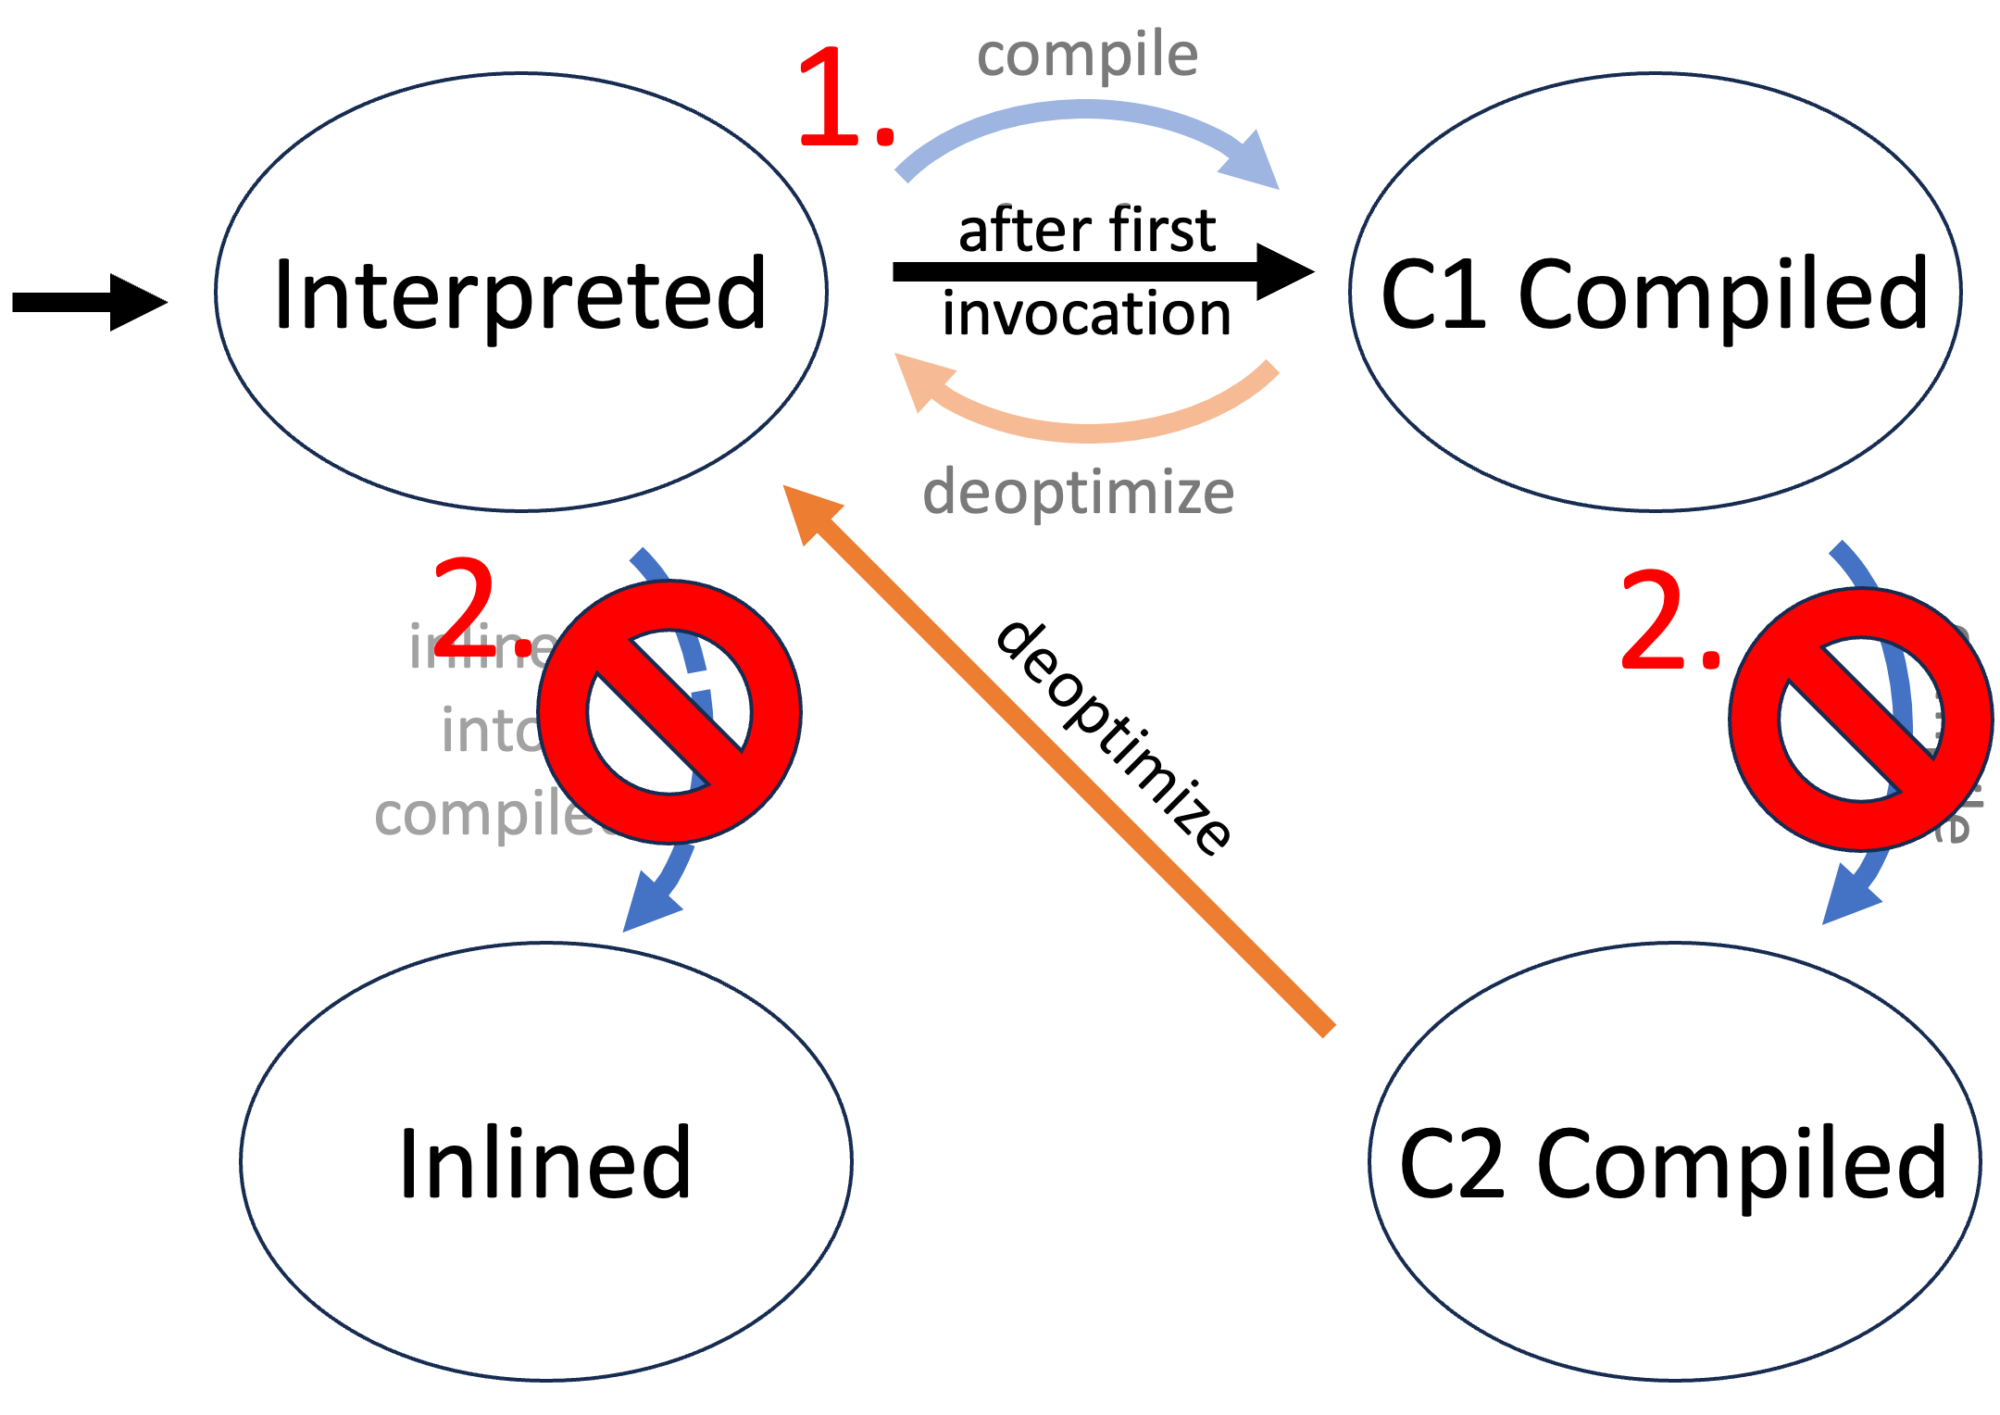
The first time the JVM executes a method, the method’s byte code is interpreted without compilation. This allows the JVM to gather information on the method, as C1 and C2 are profile guided.
The method is then compiled when the JVM deems this to be beneficial, usually after the method has been executed a few times. The next call of the method will then use the compiled version. The method is initially compiled with different levels of the C1 compiler before finally being C2 compiled, which takes the longest but produces the best native instructions.
The JVM might decide at any point to use the interpreted version of a method by deoptimizing it. The compiled versions are kept, depending on the compiler and the reasons for the deoptimization.
Every compiler can decide to inline called methods of a currently compiled method. A compiler uses the initial byte code for this purpose.
What we want and what we get
The ideal would be to tell the JVM to just use a method in its compiled version, e.g.:
But this is not possible, as the JVM does not have any information it needs for compilation before the first execution of a method. We, therefore, have first to execute the method (or the benchmark) and then set the compilation level:
How do we get it?
We can split the task of forcing a method to be compiled (or inlined, for that matter) into two parts:
Force all methods into their respective state (→ WhiteBox API) after the initial execution.
Force the JIT to never compile a method with a different compiler (→ Compiler Control)
The following is the modified state diagram when forcing a method to be C1 compiled:
In the following, I’ll discuss how to use both the WhiteBox API and Compiler Control to facilitate the wanted behavior.
WhiteBox API
Many JVM tests are written in the JTreg framework, allowing developers to write these tests in Java. But these tests often require specific functionality not regularly available to Java developers. This functionality is exported in the WhiteBox API:
One of the not so well-known tools of the HotSpot VM is its WhiteBox testing API. Introduced in Java 7 it has been significantly improved and extended in Java 8 and 9. It can be used to query or change HotSpot internals which are not otherwise exposed to Java-land. While its features make it an indispensable tool for writing good HotSpot regression tests, it can also be used for experiments or for the mere fun of peeking into the VM. This entry will focus on the usage of the WhiteBox API in Java 8 and 9.
The WhiteBox API is implemented as a Java class (called sun.hotspot.WhiteBox) which defines various entry points into the HotSpot VM. Most of the functionality is implemented natively, directly in the HotSpot VM. The API is implemented as a singleton which can be easily retrieved by calling the static method WhiteBox.getWhiteBox().
Unfortunately, currently even a simple JavaDoc documentation of the API doesn’t exist, so in order to make full use of its functionality, you’ll have to peek right into WhiteBox.java.
This API can be used outside of JTreg tests after enabling it by passing -Xbootclasspath/a:wb.jar -XX:+UnlockDiagnosticVMOptions -XX:+WhiteBoxAPI as JVM arguments. To use it, you have to build the WhiteBox JAR from scratch for your specific JVM by calling make build-test-lib (after you set up the build via the configure script).
But please be aware that using this API outside of JVM tests is relatively rare, and the documentation is still non-existent, so using it entails reading a lot of JDK sources and experimentation.
The build target did not work in JDK 21, and when I fixed it, the first question in the PR was by Daniel Jelinski, who asked:
That’s interesting. How did you find this? Is the result of this target used anywhere? As far as I could tell, the build-test-lib target itself is not used anywhere. The classes that fail to compile here are used by tests without any problems – each test specifies the necessary imports individually. Should we remove this make target instead?
So it would be best if you certainly did not depend on it.
The WhiteBox API consists of the singleton class jdk.test.whitebox.WhiteBox which offers many methods: From GC related methods like boolean isObjectInOldGen(Object o) and void fullGC() to NMT-related methods like long NMTMalloc(long size) and JIT-related methods like void deoptimizeAll().
You can even use it to force the compilation of a method and to set JVM flags, as shown in this example by Jean-Philippe Bempel:
This is from his blog post WhiteBox API, the only blog post I could find on this topic.
Back to our goal of forcing the compilation of a method. It is a good idea to reset the state of a method and deoptimize it to start from a blank slate:
// obtain a method reference
Executable m = X.class.getDeclaredMethod("m", null);
// obtain a WhiteBox instance
WhiteBox wb = WhiteBox.getWhiteBox();
// deooptimize the method
wb.deoptimizeMethod(m);
// clear its state, found by experimentation to be neccessary
wb.clearMethodState(m);
We can then either leave the method uncompiled (for compilation level 0) or enqueue for compilation:
I implemented this in the WhiteBoxUtil class in my trace-tester library. This allows us to force all methods in their respective states. But the JVM can still decide to optimize further or inline a method, even when specifying the contrary. So we have to force the JVM using the second the Compiler Control specifications.
Compiler Control
This control mechanism has been introduced in Java 9 with JEP 165 by Nils Eliasson:
Summary
This JEP proposes an improved way to control the JVM compilers. It enables runtime manageable, method dependent compiler flags. (Immutable for the duration of a compilation.)
Goals
Fine-grained and method-context dependent control of the JVM compilers (C1 and C2)
The ability to change the JVM compiler control options in run time
No performance degradation
Motivation
Method-context dependent control of the compilation process is a powerful tool for writing small contained JVM compiler tests that can be run without restarting the entire JVM. It is also very useful for creating workarounds for bugs in the JVM compilers. A good encapsulation of the compiler options is also good hygiene.
This mechanism is properly standardized for the OpenJDK, unlike the WhiteBox APi. The compiler control allows to specify compilation settings by defining them in a JSON file and applying them:
Using jcmd (see JEP): jcmd <pid> Compiler.add_directives <file>
Passing it via JVM arguments: -XX:+UnlockDiagnosticVMOptions -XX:CompilerDirectivesFile=<file>
Using the WhiteBox API: int addCompilerDirective(String compDirect)
The following directives specify as an example that the method m should not be C2 compiled and not be inlined:
[
  {
    // can also contain patterns
    "match": ["X::m()"],
    // "-" prefixes not inlined, "+" inlined methods
    "inline": ["-X::m()"],
    "C1": {},
    "C2": {
      "Exclude": true
    }
  }
  // multiple directives supported
  // first directives have priority
]
This, in theory, allows the method to be deoptimized, but this did not happen during my testing. With forced compilation, one can assume that this method will almost be used in its compiled form.
I recommend this Compiler Control guide for a more in-depth guide with all options. An implementation of the control file generation with a fluent API can be found in the trace-tester project in the CompilerDirectives class. Feel free to adapt this for your own projects.
Conclusion
I’ve shown you in this article how to control the JIT to specify the inlining and compilation of methods using two lesser-known JVM APIs. This allows us to write reproducible profiling APIs and makes it easier to check how a profiling API reacts to different scenarios.
If you have any suggestions, feel free to reach out. I look forward to preparing slides for my upcoming talks in Milan, Munich, Arnhem, and Karlsruhe. Feel free to come to my talks; more information soon on Twitter.
This project is part of my work in the SapMachine team at SAP, making profiling easier for everyone.
Using async-profiler and jattach can be quite a hassle. First, you have to download the proper archive from GitHub for your OS and architecture; then, you have to unpack it and place it somewhere. It gets worse if you want to embed it into your library, agent, or application: Library developers cannot just use maven dependency but have to create wrapper code and build scripts that deal with packaging the binaries themselves, or worse, they depend on a preinstalled version which they do not control.
In November 2022, I started the ap-loader project to remedy this situation: I wrapped async-profiler and jattach in a platform-independent JAR which can be pulled from maven central. I already wrote a blog post on its essential features: AP-Loader: A new way to use and embed async-profiler.
In this blog post, I’m focusing on its programmatic usage: Async-profiler can be used in a library to gather profiling data of the current or a different process, but the profiler distribution contains more: It contains converters to convert from JFR to flamegraphs, and jattach to attach a native agent dynamically to (potentially the current) JVM and send commands to it.
This blog post does assume that you’re familiar with the basic usage of async-profiler. If you are not, consider reading the async-profiler README or the Async-profiler – manual by use cases by Krzysztof Ślusarski.
The ap-loader library allows you to depend on a specific version of async-profiler using gradle or maven:
There are multiple maven artifacts: ap-loader-all which contains the native libraries for all platforms for which async-profiler has pre-built libraries and artifacts that only support a single platform like ap-loader-macos. I recommend using the ap-loader-all if you don’t know what you’re doing, the current release is still tiny, with 825KB.
The version number consists of the async-profiler version and the version (here 2.9) of the ap-loader support libraries (here 5). I’m typically only publishing the newest ap-loader version for the latest async-profiler. The changes in ap-loader are relatively minimal, and I keep the API stable between versions.
The ap-loader library consists of multiple parts:
AsyncProfilerLoader class: Wraps async-profiler and jattach, adding a few helper methods
converter package: Contains all classes from the async-profiler converter JAR and helps to convert between multiple formats
AsyncProfiler class: API for async-profiler itself, wrapping the native library.
All but the AsyncProfilerLoader class is just copied from the underlying async-profiler release. ap-loader contains all Java classes from async-profiler, but I omit the helper classes here for brevity.
AsyncProfilerLoader
This is the main entry point to ap-loader; it lives in the one.profiler package like the AsyncProfiler class. Probably the most essential method is load:
Load
The load method loads the included async-profiler library for the current platform:
It returns the instantiated API wrapper class. The method throws an IllegalStateException if the present ap-loader dependencies do not support the platform and an IOException if loading the library resulted in other problems.
Newer versions of the AsyncProfiler API contain the AsyncProfiler#getInstance() method, which can also load an included library. The main difference is that you have to include the native library for all the different platforms, replicating all the work of the ap-loader build system every time you update async-profiler.
Dealing with multiple platforms is hard, and throwing an exception when not supporting a platform might be inconvenient for your use case. AsyncProfilerLoader has the loadOrNull method which returns null instead and also the isSupported to check whether the current combination of OS and CPU is supported. A typical use case could be:
if (AsyncProfilerLoader.isSupported()) {
  AsyncProfilerLoader.load().start(...);
} else {
  // use JFR or other fall-backs
}
This might still throw IOExceptions, but they should never happen in normal circumstances and are probably by problems that should be investigated, being either an error in ap-loader or in your application.
If you want to merely get the path to the extracted libAsyncProfiler, then use the getAsyncProfilerPath method which throws the same exceptions as the load method. A similar method exists for jattach (getJattachPath).
Execute Profiler
The async-profiler project contains the profiler.sh script (will be replaced by asprof starting with async-profiler 2.10):
To run the agent and pass commands to it, the helper script profiler.sh is provided. A typical workflow would be to launch your Java application, attach the agent and start profiling, exercise your performance scenario, and then stop profiling. The agent’s output, including the profiling results, will be displayed in the Java application’s standard output.
This helper script is also included in ap-loader and allows you to use the script on the command-line via java -jar ap-loader profiler ..., the API exposes this functionality via ExecutionResult executeProfiler(String... args).
AsyncProfilerLoader.executeProfiler("-e", "wall", "8983")
// is equivalent to
./profiler.sh -e wall -t -i 5ms -f result.html 8983
The executeProfiler method throws an IllegalStateException if the current platform is not supported. The returned instance of ExecutionResult contains the standard and error output:
public static class ExecutionResult {
  private final String stdout;
  private final String stderr;
    // getter and constructor
    ...
}
executeProfiler throws an IOException if the profiler execution failed.
Execute Converter
You cannot only use the converter by using the classes from the one.profiler.converter, but you can also execute the converter by calling ExecutionResult executeProfiler(String... args), e.g., the following:
AsyncProfilerLoader.executeConverter(
  "jfr2flame", "<input.jfr>", "<output.html>")
// is equivalent to
java -cp converter.jar \
  jfr2flame <input.jfr> <output.html>
The executeConverter returns the output of the conversion tool on success and throws an IOException on error, as before.
JAttach
There are multiple ways to use the embedded jattach besides using the binary returned by getJattachPath: ExecutionResult executeJattach(String... args) and boolean jattach(Path agentPath[, String arguments]).
executeJattach works similar to executeProfiler, e.g.:
AsyncProfilerLoader.executeJattach(
  "<pid>", "load", "instrument", "false", "javaagent.jar=arguments")
// is equivalent to
jattach <pid> load instrument false "javaagent.jar=arguments"
This runs the same as jattach with the only exception that every string that ends with libasyncProfiler.so is mapped to the extracted async-profiler library for the load command. One can, therefore, for example, start the async-profiler on a different JVM via the following:
But this use case can, of course, be accomplished by using the executeProfiler method, which internally uses jattach.
A great use case for jattach is to attach a custom native agent to the currently running JVM. Starting with JVM 9 doing this via VirtualMachine#attachthrows an IOException if you try this without setting -Djdk.attach.allowAttachSelf=true. The boolean jattach(Path agentPath[, String arguments]) methods simplify this, constructing the command line arguments for you and returning true if jattach succeeded, e.g.:
AsyncProfilerLoader.jattach("libjni.so")
This attaches the libjni.so agent to the current JVM. The process id of this JVM can be obtained by using the getProcessId method.
Extracting a Native Library
I happen to write many small projects for testing profilers that often require loading a native library from the resources folder; an example can be found in the trace_validation (blog post) project:
/**
 * extract the native library and return its temporary path
 */
public static synchronized Path getNativeLibPath(
 ClassLoader loader) {
  if (nativeLibPath == null) {
    try {
      String filename = System.mapLibraryName(NATIVE_LIB);
      InputStream in = loader.getResourceAsStream(filename);
      // ...
    } catch (IOException e) {
      throw new RuntimeException(e);
    }
  }
  return nativeLibPath;
}
I, therefore, added the extractCustomLibraryFromResources method:
/**
 * Extracts a custom native library from the resources and
 * returns the alternative source if the file is not
 * in the resources.
 *
 * If the file is extracted, then it is copied to
 * a new temporary folder which is deleted upon JVM exit.
 *
 * This method is mainly seen as a helper method
 * to obtain custom native agents for #jattach(Path) and
 * #jattach(Path, String). It is included in ap-loader
 * to make it easier to write applications that need
 * custom native libraries.
 *
 * This method works on all architectures.
 *
 * @param classLoader the class loader to load
 *                 the resources from
 * @param fileName the name of the file to copy,
 *                 maps the library name if the fileName
 *                 does not start with "lib", e.g. "jni"
 *                 will be treated as "libjni.so" on Linux
 *                 and as "libjni.dylib" on macOS
 * @param alternativeSource the optional resource directory
 *                 to use if the resource is not found in
 *                 the resources, this is typically the case
 *                 when running the application from an IDE,
 *                 an example would be "src/main/resources"
 *                 or "target/classes" for maven projects
 * @return the path of the library
 * @throws IOException if the extraction fails and
 *                  the alternative source is not present
 *                  for the current architecture
 */
public static Path extractCustomLibraryFromResources(
  ClassLoader classLoader, String fileName,
  Path alternativeSource) throws IOException
This can be used effectively together with jattach to attach a native agent from the resources to the current JVM:
// extract the agent first from the resources
Path p = one.profiler.AsyncProfilerLoader.
  extractCustomLibraryFromResources(
    ....getClassLoader(), "library name");
// attach the agent to the current JVM
one.profiler.AsyncProfilerLoader.jattach(p, "optional arguments")
// -> returns true if jattach succeeded
This use-case comes from a profiler test helper library on which I hope to write a blog post in the near future.
Conclusion
ap-loader makes it easy to use async-profiler and its included tools programmatically without creating complex build systems. The project is regularly updated to keep pace with the newest stable async-profiler version; updating a version just requires changing a single dependency in your dependencies list.
The ap-loader is mature, so try it and tell me about it. I’m happy to help with any issues you have with this library, so feel free to write to me or create an issue on GitHub.
This project is part of my work in the SapMachine team at SAP, making profiling easier for everyone.
This blog post is about writing a Java agent and instrumentation code to find unused classes and dependencies in your project. Knowing which classes and dependencies are not used in your application can save you from considering the bugs and problems in these dependencies and classes if you remove them.
There a multiple tools out there, for gradle and maven (thanks, Marit), that do this statically or dynamically (like the one described in the paper Coverage-Based Debloating for Java Bytecode, thanks, Wolfram). Statical tools are based on static program analysis and are usually safer, as they only remove classes that can statically be proven never to be used. But these tools generally struggle with reflection and code generation which frameworks like Spring use heavily. Dynamic tools typically instrument the bytecode of the Java application and run it to see which parts of the application are used in practice. These tools can deal with recursion and are more precise, removing larger portions of the code.
The currently available tools maybe suffice for your use case, but they are complex software, hard to reason about, and hard to understand. Therefore, this post aims to write a prototypical dynamic tool to detect unused classes. This is like the profiler of my Writing a Profiler in 240 Lines of Pure Java blog post, done mainly for educational purposes, albeit the tool might be helpful in certain real-world use cases. As always, you can find the final MIT-licensed code on GitHub in my dead-code-agent repository.
Main Idea
I make one simplification compared to many of the more academic tools: I only deal with code with class-level granularity. This makes it far more straightforward, as it suffices to automatically instrument the static initializers of every class (and interface), turning
class A {
    private int field;
    public void method() {...}
}
into
class A {
    static {
       Store.getInstance().processClassUsage("A");
    }
    private int field;
    public void method() {...}
}
to record the first usage of the class A in a global store. Another advantage is that there is minimal overhead when recording the class usage information, as only the first usage of every class has the recording overhead.
Static initializers are called whenever a class is initialized, which happens in the following circumstances:
A class or interface T will be initialized immediately before the first occurrence of any one of the following:
T is a class and an instance of T is created.
A static method declared by T is invoked.
A static field declared by T is assigned.
A static field declared by T is used and the field is not a constant variable (§4.12.4).
When a class is initialized, its superclasses are initialized (if they have not been previously initialized), as well as any superinterfaces (§8.1.5) that declare any default methods (§9.4.3) (if they have not been previously initialized). Initialization of an interface does not, of itself, cause initialization of any of its superinterfaces.
Adding code at the beginning of every class’s static initializers lets us obtain knowledge on all used classes and interfaces. Interfaces don’t have static initializers in Java source code, but the bytecode supports this nonetheless, and we’re only working with bytecode here.
We can then use this information to either remove all classes that are not used from the application’s JAR or log an error message whenever such a class is instantiated:
class UnusedClass {
    static {
       System.err.println("Class UnusedClass is used " +
                          "which is not allowed");
    }
    private int field;
    public void method() {...}
}
This has the advantage that we still log when our assumption on class usage is broken, but the program doesn’t crash, making it more suitable in production settings.
Structure
The tool consists of two main parts:
Instrumenter: Instruments the JAR and removes classes, used both for modifying the JAR to obtain the used classes and to remove unused classes or add error messages (as shown above)
Instrumenting Agent: This agent is similar to the Instrumenter but is implemented as an instrumenting Java agent. Both instrumentation methods have advantages and disadvantages, which I will explain later.
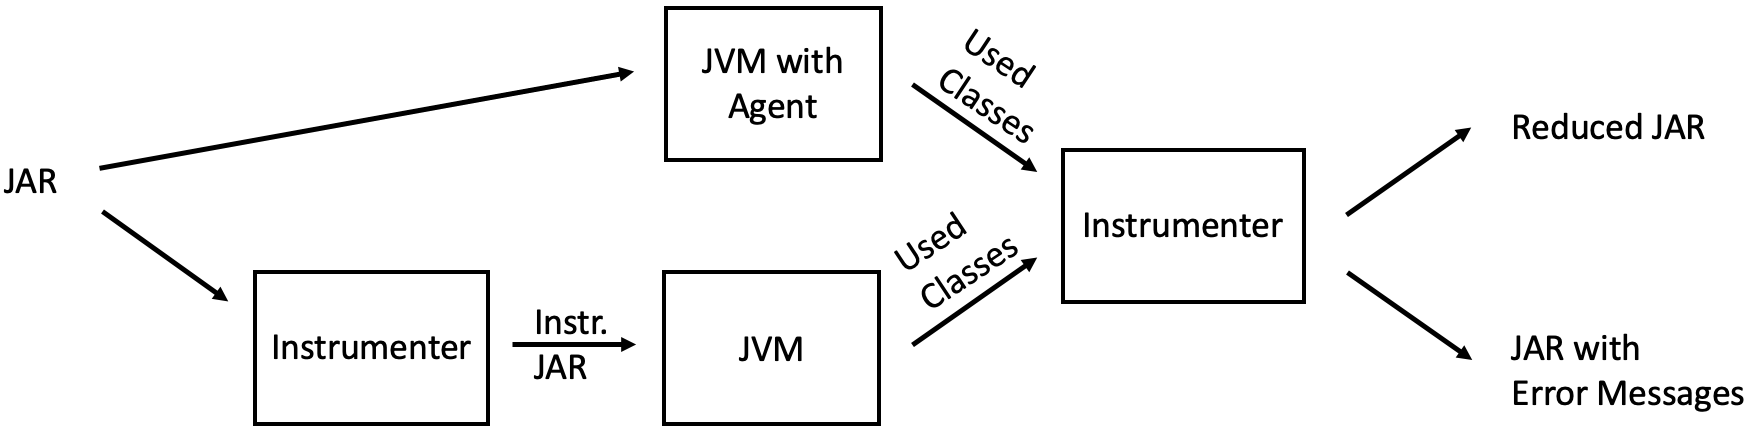
This leads us to the following workflow:
Workflow of the dead-code analyzer
Usage
Before I dive into the actual code, I’ll present you with how to use the tool. Skip this section if you’re only here to see how to implement an instrumenting agent 🙂
You first have to download and build the tool:
git clone https://github.com/parttimenerd/dead-code-agent
cd dead-code-agent
mvn package

# and as demo application the spring petclinic
git clone https://github.com/spring-projects/spring-petclinic
cd spring-petclinic
mvn package
# make the following examples more concise
cp spring-petclinic/target/spring-petclinic-3.0.0-SNAPSHOT.jar \
   petclinic.jar
The tool is written in Java 17 (you should be using this version anyways), which is the only system requirement.
Using the Instrumenting Agent to Obtain the Used Classes
The instrumenting agent can be started at JVM startup:
This will record all loaded and used classes in the classes.txt file, which includes lines like:
u ch.qos.logback.classic.encoder.PatternLayoutEncoder
l ch.qos.logback.classic.joran.JoranConfigurator
u ch.qos.logback.classic.jul.JULHelper
u ch.qos.logback.classic.jul.LevelChangePropagator
Telling you that the PatternLayoutEncoder class has been used and has only been loaded but not used. Loaded means, in our context, that the instrumenting agent instrumented this class.
Not all classes can be instrumented. It is impossible to, for example, add static initializers to the class that we loaded before the instrumentation agent started; this is not a problem, as we can start the agent just after all JDK classes have been loaded. Removing JDK classes is possible with jlink, but instrumenting these classes is out-of-scope for this article, as they are far harder to instrument and most people don’t consider these classes.
The instrumentation agent is not called for some Spring Boot classes for reasons unknown to me. This makes the agent approach unsuitable for Spring Boot applications and led me to the development of the main instrumenter:
Using the Instrumenter to Obtain the Used Classes
The instrumenter lets you create an instrumented JAR that records all used classes:
This will throw a few errors, but remember; it’s still a prototype.
You can then run the resulting JAR to obtain the list of used classes (like above). Just use the instrumented.jar like your application JAR:
java -jar instrumented.jar
The resulting classes.txt is similar to the file produced by the instrumenting agent. The two differences are that we cannot observe only loaded but not used classes and don’t miss any Spring-related classes. Hopefully, I will find time to investigate the issue related to Spring’s classloaders.
Using the Instrumenter to Log Usages of Unused Classes
The list of used classes can be used to log the usage of classes not used in the recording runs:
This will log the usage of all classes not marked as used in classes.txt on standard error, or exit the program if you pass the --exit option to the instrumenter.
If you, for example, recorded the used classes of a run where you did not access the petclinic on localhost:8080, then executing the modified logging.jar and accessing the petclinic results in output like:
Class org.apache.tomcat.util.net.SocketBufferHandler is used which is not allowed
Class org.apache.tomcat.util.net.SocketBufferHandler$1 is used which is not allowed
Class org.apache.tomcat.util.net.NioChannel is used which is not allowed
Class org.apache.tomcat.util.net.NioChannel$1 is used which is not allowed
...
An exciting feature of the instrumenter is that the file format of the used classes file is not restricted to what the instrumented JARs produce. It also supports wild cards:
u org.apache.tomcat.*
Tells the instrumenter that all classes which have a fully-qualified name starting with org.apache.tomcat. should be considered used.
r org.apache.* used apache
This tells the instrumenter to instrument the JAR to report all usages of Apache classes, adding the (optional) message “used apache.”
These two additions make the tool quite versatile.
Writing the Instrumentation Agent
We start with the instrumentation agent and later go into the details of the Instrumenter.
The agent itself consists of three major parts:
Main class: Entry point for the agent, registers the ClassTransformer as a transformer
ClassTransformer class: Instruments all classes as described before
Store class: Deals with handling and storing the information on used and stored classes
A challenge here is that all instrumented classes will use the Store. We, therefore, have to put the store onto the bootstrap classpath, making it visible to all classes. There are multiple ways to do this:
It is building a runtime JAR directly in the agent using the JarFile API, including the bytecode of the Store and its inner classes.
Building an additional dead-code-runtime.jar using a second maven configuration, including this JAR as a resource in our agent JAR, and copying it into a temporary file in the agent.
Both approaches are valid, but the second approach seems more widely used, and the build system includes all required classes and warns of missing ones.
We build the runtime JAR by creating a new maven configuration that only includes the me.bechberger.runtime package where the Store resides:
The main class consists mainly of the premain method which deletes the used classes file, loads the runtime JAR, and registers the ClassTransformer:
public class Main {

    public static void premain(String agentArgs,
      Instrumentation inst) {
        AgentOptions options = new AgentOptions(agentArgs);
        // clear the file
        options.getOutput().ifPresent(out -> {
            try {
                Files.deleteIfExists(out);
                Files.createFile(out);
            } catch (IOException e) {
                throw new RuntimeException(e);
            }
        });
        try {
            inst.appendToBootstrapClassLoaderSearch(
                new JarFile(getExtractedJARPath().toFile()));
        } catch (IOException e) {
            throw new RuntimeException(e);
        }
        inst.addTransformer(new ClassTransformer(options), true);
    }
    // ...
}
I’m omitting the AgentOptions class, which parses the options passed to the agent (like the output file).
The premain method uses the getExtractedJARPath method to extract the runtime JAR. This extracts the JAR from the resources:
    private static Path getExtractedJARPath() throws IOException {
        try (InputStream in = Main.class.getClassLoader()
                 .getResourceAsStream("dead-code-runtime.jar")){
            if (in == null) {
                throw new RuntimeException("Could not find " +
                    "dead-code-runtime.jar");
            }
            File file = File.createTempFile("runtime", ".jar");
            file.deleteOnExit();
            Files.copy(in, file.toPath(),
                       StandardCopyOption.REPLACE_EXISTING);
            return file.toPath().toAbsolutePath();
        }
    }
ClassTransformer Class
This transformer implements the ClassFileTransformer to transform all loaded classes.
A transformer of class files. An agent registers an implementation of this interface using the addTransformer method so that the transformer’s transform method is invoked when classes are loaded, redefined, or retransformed. The implementation should override one of the transform methods defined here. Transformers are invoked before the class is defined by the Java virtual machine.
We could do all the bytecode modification ourselves. This is error-prone and complex, so we use the Javassist library, which provides a neat API to insert code into various class parts.
Our ClassTransformer has to implement the transform method:
Transforms the given class file and returns a new replacement class file.
Parameters:
module – the module of the class to be transformed
loader – the defining loader of the class to be transformed, may be null if the bootstrap loader
className – the name of the class in the internal form of fully qualified class and interface names as defined in The Java Virtual Machine Specification. For example, "java/util/List".
classBeingRedefined – if this is triggered by a redefine or retransform, the class being redefined or retransformed; if this is a class load, null
protectionDomain – the protection domain of the class being defined or redefined
classfileBuffer – the input byte buffer in class file format – must not be modified
This prevents instrumentation problems and keeps the list of used classes clean. We then use a statically defined ScopedClassPoolFactory to create a class pool for the given class loader, parse the bytecode using javassist and transform it using our transform(String className, CtClass cc) method:
        try {
            ClassPool cp = scopedClassPoolFactory
                 .create(loader, ClassPool.getDefault(),
                         ScopedClassPoolRepositoryImpl
                             .getInstance());
            CtClass cc = cp.makeClass(
                 new ByteArrayInputStream(classfileBuffer));
            if (cc.isFrozen()) {
                // frozen classes cannot be modified
                return classfileBuffer;
            }
            // classBeingRedefined is null in our case
            transform(className, cc);
            return cc.toBytecode();
        } catch (CannotCompileException | IOException |
                 RuntimeException | NotFoundException e) {
            e.printStackTrace();
            return classfileBuffer;
        }
The actual instrumentation is now done with the javassist API:
    private void transform(String className, CtClass cc)
      throws CannotCompileException, NotFoundException {
        // replace "/" with "." in the className
        String cn = formatClassName(className);
        // handle the class load
        Store.getInstance().processClassLoad(cn,
            cc.getClassFile().getInterfaces());
        // insert the call to processClassUsage at the beginning
        // of the static initializer
        cc.makeClassInitializer().insertBefore(
             String.format("me.bechberger.runtime.Store" +
                 ".getInstance().processClassUsage(\"%s\");",
                 cn));
    }
You might wonder why we’re also recording the interfaces of every class. This is because the static initializers of interfaces are not called when the first static initializer of an implemented class is called. We, therefore, have to walk the interface tree ourselves. Static initializers of parent classes are called; therefore, we don’t have to handle parent classes ourselves.
Instrumenter
The main difference is that the instrumenter also transforms the bytecode, transforming all files in the JAR and writing a new JAR back. This new JAR is then executed, which has the advantage that we can instrument all classes in the JAR (even with Spring’s classloader magic). The central part of the Instrumenter is the ClassAndLibraryTransformer which can be targeted to a specific class transformation use case by setting its different fields:
public class ClassAndLibraryTransformer {
    /** Source JAR */
    private final Path sourceFile;
    /**
     * Include a library in the output JAR.
     * A library is JAR inside this JAR and
     * its name is the file name without version identifier
     * and suffix.
     */
    private Predicate<String> isLibraryIncluded;
    /** Include a class in the output JAR */
    private Predicate<String> isClassIncluded;
    /**
     * Transforms the class file, might be null.
     * Implemented using the javassist library as shown before.
     */
    private BiConsumer<ClassPool, CtClass> classTransformer;

    record JarEntryPair(String name, InputStream data) {
        static JarEntryPair of(Class<?> klass, String path)
          throws IOException {
            // obtain the bytecode from the dead-code JAR
            return new JarEntryPair(path,
                klass.getClassLoader().getResourceAsStream(path));
        }
    }
    /**
     * Supplies a list of class files that should
     * be added to the JAR, like the Store related classes
     */
    private Supplier<List<JarEntryPair>> miscFilesSupplier =
         List::of;
    /** Output JAR */
    private final OutputStream target;
    // ...
}
This class is used for instrumentation and removing classes and nested JARs/libraries, sharing most of the code between both.
The central entry point of this class is the process method, which iterates over all entries of the sourceFile JAR using the JarFile and JarOutputStream APIs:
    void process(boolean outer) throws IOException {
        try (JarOutputStream jarOutputStream =
             new JarOutputStream(target);
            JarFile jarFile = new JarFile(sourceFile.toFile())) {
            jarFile.stream().forEach(jarEntry -> {
                try {
                    String name = jarEntry.getName();
                    if (name.endsWith(".class")) {
                        processClassEntry(jarOutputStream,
                            jarFile, jarEntry);
                    } else if (name.endsWith(".jar")) {
                        processJAREntry(jarOutputStream,
                            jarFile, jarEntry);
                    } else {
                        processMiscEntry(jarOutputStream,
                            jarFile, jarEntry);
                    }
                } catch (IOException e) {
                    // .forEach forces us to wrap exceptions
                    throw new RuntimeException(e);
                }
            });
            if (outer) { // add miscellaneous class files
                for (JarEntryPair miscFile :
                        miscFilesSupplier.get()) {
                    // create a new entry
                    JarEntry jarEntry =
                        new JarEntry(miscFile.name);
                    jarOutputStream.putNextEntry(jarEntry);
                    // add the file contents
                    miscFile.data.transferTo(jarOutputStream);
                }
            }
        }
    }
Processing entries of the JAR file that are neither class files nor JARs consist only of copying the entry directly to the new file:
Such files are typically resources like XML configuration files.
Transforming class file entries is slightly more involved: We check whether we should include the class defined in the class file and transform it if necessary:
    private void processClassEntry(
      JarOutputStream jarOutputStream,
      JarFile jarFile, JarEntry jarEntry) throws IOException {
        String className = classNameForJarEntry(jarEntry);
        if (isClassIncluded.test(className) ||
              isIgnoredClassName(className)) {
            jarOutputStream.putNextEntry(jarEntry);
            InputStream classStream =
                jarFile.getInputStream(jarEntry);
            if (classTransformer != null &&
                  !isIgnoredClassName(className)) {
                // transform if possible and required
                classStream = transform(classStream);
            }
            classStream.transferTo(jarOutputStream);
        } else {
            System.out.println("Skipping class " + className);
        }
    }
We ignore here class files related to package-info or module-info, as they don’t contain valid classes. This is encapsulated in the isIgnoredClassName method. The implementation of the transform method is similar to the transform method of the instrumenting agent, using the classTransformer consumer for the actual class modification.
A transforming consumer to log the usage of every unused class looks as follows, assuming that isClassUsed it is a predicate that returns true if the passed class is used and that messageSupplier supplies specific messages that are output additionally:
(ClassPool cp, CtClass cc) -> {
    String className = cc.getName();
    if (isClassUsed.test(className)) {
        return;
    }
    try {
        String message = messageSupplier.apply(className);
        cc.makeClassInitializer().insertBefore(
            String.format("System.err.println(\"Class %s " +
                          "is used which is not allowed%s\");" +
                          "if (%s) { System.exit(1); }",
                className,
                message.isBlank() ? "" : (": " + message),
                exit));
    } catch (CannotCompileException e) {
        throw new RuntimeException(e);
    }
};
The last thing that I want to cover is the handling of nested JARs in the processJAREntry(JarOutputStream jarOutputStream, JarFile jarFile, JarEntry jarEntry) method. Nested JARs are pretty standard with Spring and bundle libraries with your application. To quote the Spring documentation:
Java does not provide any standard way to load nested jar files (that is, jar files that are themselves contained within a jar). This can be problematic if you need to distribute a self-contained application that can be run from the command line without unpacking.
To solve this problem, many developers use “shaded” jars. A shaded jar packages all classes, from all jars, into a single “uber jar”. The problem with shaded jars is that it becomes hard to see which libraries are actually in your application. It can also be problematic if the same filename is used (but with different content) in multiple jars. Spring Boot takes a different approach and lets you actually nest jars directly.
Our method first checks that we should include the nested JAR and, if so, extract it into a temporary file. We extract the JAR because the JarFile API can only work with files. We then use the ClassAndLibraryTransformer recursively:
    private void processJAREntry(JarOutputStream jarOutputStream,
      JarFile jarFile, JarEntry jarEntry) throws IOException {
        String name = jarEntry.getName();
        String libraryName = Util.libraryNameForPath(name);
        if (!isLibraryIncluded.test(libraryName)) {
            System.out.println("Skipping library " + libraryName);
            return;
        }
        Path tempFile = Files.createTempFile("nested-jar", ".jar");
        tempFile.toFile().deleteOnExit();
        // copy entry over
        InputStream in = jarFile.getInputStream(jarEntry);
        Files.copy(in, tempFile,
                   StandardCopyOption.REPLACE_EXISTING);
        ClassAndLibraryTransformer nestedJarProcessor;
        // create new JAR file
        Path newJarFile = Files.createTempFile("new-jar",
                                               ".jar");
        newJarFile.toFile().deleteOnExit();
        try (OutputStream newOutputStream =
              Files.newOutputStream(newJarFile)) {
            nestedJarProcessor =
                new ClassAndLibraryTransformer(tempFile,
                    isLibraryIncluded, isClassIncluded,
                    classTransformer,
                    newOutputStream);
                    nestedJarProcessor.process(false);
        }
        // create an uncompressed entry
        JarEntry newJarEntry = new JarEntry(jarEntry.getName());
        newJarEntry.setMethod(JarEntry.STORED);
        newJarEntry.setCompressedSize(Files.size(newJarFile));
        CRC32 crc32 = new CRC32();
        crc32.update(Files.readAllBytes(newJarFile));
        newJarEntry.setCrc(crc32.getValue());
        jarOutputStream.putNextEntry(newJarEntry);
        Files.copy(newJarFile, jarOutputStream);
    }
Nesting JAR files come with a few restrictions, but most notable is the limitation of ZIP compression:
The ZipEntry for a nested jar must be saved by using the ZipEntry.STORED method. This is required so that we can seek directly to individual content within the nested jar. The content of the nested jar file itself can still be compressed, as can any other entries in the outer jar.
Therefore, the code creates a JarEntry that is just stored and not compressed. But this requires us to compute and set the CRC and file size ourselves; this is done automatically for compressed entries.
All other code can be found in the GitHub repository of the project. Feel free to adapt the code and use it in your own projects.
Conclusion
Dynamic dead-code analyses are great for finding unused code and classes, helping to reduce the attack surface. Implementing such tools in a few lines of Java code is possible, creating an understandable tool that offers less potential of surprise for users. The tool developed in this blog post is a prototype of a dead-code analysis that could be run in production to find all used classes in a real-world setting.
Writing instrumentation agents using the JDK instrumentation APIs combined with the javassist library allows us to write a somewhat functioning agent in hours.
I hope this blog post helped you to understand the basics of finding unused classes dynamically and implementing your own instrumentation agent.
Thanks to Wolfram Fischer from SAP Security Research Germanyfor nerd-sniping me, leading me to write the tool and this blog post. This blog post is part of my work in the SapMachine team at SAP, making profiling easier for everyone.
A few months back, I started writing a profiler from scratch, and the code since became the base of my profiler validation tools. The only problem with this project: I wanted to write a proper non-safepoint-biased profiler from scratch. This is a noble effort, but it requires lots C/C++/Unix programming which is finicky, and not everyone can read C/C++ code.
For people unfamiliar with safepoint bias: A safepoint is a point in time where the JVM has a known defined state, and all threads have stopped. The JVM itself needs safepoints to do major garbage collections, Class definitions, method deoptimizations, and more. Threads are regularly checking whether they should get into a safepoint, for example, at method entry, exit, or loop backjumps. A profiler that only profiles at a safepoint have an inherent bias because it only includes frames from the locations inside methods where Threads check for a safepoint. The only advantage is that the stack-walking at safepoints is slightly less error-prone, as there are fewer mutations of heap and stack.For more information, consider reading the excellent article Java Safepoint and Async Profiling by Seetha Wenner, the more technical one by JP Bempel, or the classic article Safepoints: Meaning, Side Effects and Overheads by Nitsan Wakart. To conclude: Safepoint-biased profilers don’t give you a holistic view of your application, but can still be helpful to analyze major performance issues where you look at the bigger picture.
People on the hackernews thread on this blog post pointed out that the code has potentially some concurrency and publication issues. I’ll fixed the code in the GitHub repository, but kept the old code here. The modifications are minor.
This blog post aims to develop a tiny Java profiler in pure Java code that everyone can understand. Profilers are not rocket science, and ignoring safepoint-bias, we can write a usable profiler that outputs a flame graph in just 240 lines of code.
You can find the whole project on GitHub. Feel free to use it as a base for your adventures (and if you do, feel free to write me on Twitter, where I regularly post on profiling-related topics).
We implement the profiler in a daemon thread started by a Java agent. This allows us to start and run the profiler alongside the Java program we want to profile. The main parts of the profiler are:
Main: Entry point of the Java agent and starter of the profiling thread
Options: Parses and stores the agent options
Profiler: Contains the profiling loop
Store: Stores and outputs the collected results
Main Class
We start by implementing the agent entry points:
public class Main {
    public static void agentmain(String agentArgs) {
        premain(agentArgs);
    }

    public static void premain(String agentArgs) {
        Main main = new Main();
        main.run(new Options(agentArgs));
    }

    private void run(Options options) {
        Thread t = new Thread(new Profiler(options));
        t.setDaemon(true);
        t.setName("Profiler");
        t.start();
    }
}
The premain is called when the agent is attached to the JVM at the start. This is typical because the user passed the -javagent to the JVM. In our example, this means that the user runs Java with
But there is also the possibility that the user attaches the agent at runtime. In this case, the JVM calls the method agentmain. To learn more about Java agent, visit the JDK documentation.
Please be aware that we have to set the Premain-Class and the Agent-Class attributes in the MANIFEST file of our resulting JAR file.
Our Java agent parses the agent arguments to get the options. The options are modeled and parsed by the Options class:
The exciting part of the Main class is its run method: The Profiler class implements the Runnable interface so that we can create a thread directly:
Thread t = new Thread(new Profiler(options));
We then mark the profiler thread as a daemon thread; this means that the JVM does terminate at the end of the profiled application even when the profiler thread is running:
t.setDaemon(true);
No, we’re almost finished; we only have to start the thread. Before we do this, we name the thread, this is not required, but it makes debugging easier.
t.setName("Profiler");
t.start();
Profiler Class
The actual sampling takes place in the Profiler class:
public class Profiler implements Runnable {
    private final Options options;
    private final Store store;

    public Profiler(Options options) {
        this.options = options;
        this.store = new Store(options.getFlamePath());
        Runtime.getRuntime().addShutdownHook(new Thread(this::onEnd));
    }

    private static void sleep(Duration duration) {
        // ...
    }

    @Override
    public void run() {
        while (true) {
            Duration start = Duration.ofNanos(System.nanoTime());
            sample();
            Duration duration = Duration.ofNanos(System.nanoTime())
                                        .minus(start);
            Duration sleep = options.getInterval().minus(duration);
            sleep(sleep);
        }
    }

    private void sample() {
        Thread.getAllStackTraces().forEach(
          (thread, stackTraceElements) -> {
            if (!thread.isDaemon()) {
                // exclude daemon threads
                store.addSample(stackTraceElements);
            }
        });
    }

    private void onEnd() {
        if (options.printMethodTable()) {
            store.printMethodTable();
        }
        store.storeFlameGraphIfNeeded();
    }
We start by looking at the constructor. The interesting part is
which causes the JVM to call the Profiler::onEnd when it shuts down. This is important as the profiler thread is silently aborted, and we still want to print the captured results. You can read more on shutdown hooks in the Java documentation.
After this, we take a look at the profiling loop in the run method:
We use here the Thread::getAllStackTraces method to obtain the stack traces of all threads. This triggers a safepoint and is why this profiler is safepoint-biased. Taking the stack traces of a subset of threads would not make sense, as there is no method in the JDK for this. Calling Thread::getStackTrace on a subset of threads would trigger many safepoints, not just one, resulting in a more significant performance penalty than obtaining the traces for all threads.
The result of Thread::getAllStackTraces is filtered so that we don’t include daemon threads (like the Profiler thread or unused Fork-Join-Pool threads). We pass the appropriate traces to the Store, which deals with the post-processing.
Store Class
This is the last class of this profiler and also the by far most significant, post-processing, storing, and outputting of the collected information:
package me.bechberger;

import java.io.BufferedOutputStream;
import java.io.OutputStream;
import java.io.PrintStream;
import java.nio.file.Path;
import java.util.HashMap;
import java.util.List;
import java.util.Map;
import java.util.Optional;
import java.util.stream.Stream;

/**
 * store of the traces
 */
public class Store {

    /** too large and browsers can't display it anymore */
    private final int MAX_FLAMEGRAPH_DEPTH = 100;

    private static class Node {
        // ...
    }

    private final Optional<Path> flamePath;
    private final Map<String, Long> methodOnTopSampleCount =
        new HashMap<>();
    private final Map<String, Long> methodSampleCount =
        new HashMap<>();

    private long totalSampleCount = 0;

    /**
     * trace tree node, only populated if flamePath is present
     */
    private final Node rootNode = new Node("root");

    public Store(Optional<Path> flamePath) {
        this.flamePath = flamePath;
    }

    private String flattenStackTraceElement(
      StackTraceElement stackTraceElement) {
        // call intern to safe some memory
        return (stackTraceElement.getClassName() + "." +
            stackTraceElement.getMethodName()).intern();
    }

    private void updateMethodTables(String method, boolean onTop) {
        methodSampleCount.put(method,
            methodSampleCount.getOrDefault(method, 0L) + 1);
        if (onTop) {
            methodOnTopSampleCount.put(method,
                methodOnTopSampleCount.getOrDefault(method, 0L) + 1);
        }
    }

    private void updateMethodTables(List<String> trace) {
        for (int i = 0; i < trace.size(); i++) {
            String method = trace.get(i);
            updateMethodTables(method, i == 0);
        }
    }

    public void addSample(StackTraceElement[] stackTraceElements) {
        List<String> trace =
            Stream.of(stackTraceElements)
                   .map(this::flattenStackTraceElement)
                   .toList();
        updateMethodTables(trace);
        if (flamePath.isPresent()) {
            rootNode.addTrace(trace);
        }
        totalSampleCount++;
    }

    // the only reason this requires Java 17 :P
    private record MethodTableEntry(
        String method,
        long sampleCount,
        long onTopSampleCount) {
    }

    private void printMethodTable(PrintStream s,
      List<MethodTableEntry> sortedEntries) {
        // ...
    }

    public void printMethodTable() {
        // sort methods by sample count
        // the print a table
        // ...
    }

    public void storeFlameGraphIfNeeded() {
        // ...
    }
}
The Profiler calls the addSample method which flattens the stack trace elements and stores them in the trace tree (for the flame graph) and counts the traces that any method is part of.
The interesting part is the trace tree modeled by the Node class. The idea is that every trace A -> B -> C (A calls B, B calls C, [C, B, A]) when returned by the JVM) can be represented as a root node with a child node A with child B with child C, so that every captured trace is a path from the root node to a leaf. We count how many times a node is part of the trace. This can then be used to output the tree data structure for d3-flame-graph which we use to create nice flamegraphs like:
Flame graph produced by the profiler for the renaissance dotty benchmark
Keep in my mind that the actual Node class is as follows:
private static class Node {
    private final String method;
    private final Map<String, Node> children = new HashMap<>();
    private long samples = 0;

    public Node(String method) {
        this.method = method;
    }

    private Node getChild(String method) {
        return children.computeIfAbsent(method, Node::new);
    }

    private void addTrace(List<String> trace, int end) {
        samples++;
        if (end > 0) {
            getChild(trace.get(end)).addTrace(trace, end - 1);
        }
    }

    public void addTrace(List<String> trace) {
        addTrace(trace, trace.size() - 1);
    }

    /**
     * Write in d3-flamegraph format
     */
    private void writeAsJson(PrintStream s, int maxDepth) {
        s.printf("{ \"name\": \"%s\", \"value\": %d, \"children\": [",
                 method, samples);
        if (maxDepth > 1) {
            for (Node child : children.values()) {
                child.writeAsJson(s, maxDepth - 1);
                s.print(",");
            }
        }
        s.print("]}");
    }

    public void writeAsHTML(PrintStream s, int maxDepth) {
        s.print("""
                <head>
                  <link rel="stylesheet"
                   type="text/css"
                   href="https://cdn.jsdelivr.net/npm/d3-flame-graph@4.1.3/dist/d3-flamegraph.css">
                </head>
                <body>
                  <div id="chart"></div>
                  <script type="text/javascript"
                   src="https://d3js.org/d3.v7.js"></script>
                  <script type="text/javascript"
                   src="https://cdn.jsdelivr.net/npm/d3-flame-graph@4.1.3/dist/d3-flamegraph.min.js"></script>
                  <script type="text/javascript">
                  var chart = flamegraph().width(window.innerWidth);
                  d3.select("#chart").datum(""");
        writeAsJson(s, maxDepth);
        s.print("""
                ).call(chart);
                  window.onresize =
                      () => chart.width(window.innerWidth);
                  </script>
                </body>
                """);
    }
}
Tiny-Profiler
I named the final profiler tiny-profiler and its sources are on GitHub (MIT licensed). The profiler should work on any platform with a JDK 17 or newer. The usage is fairly simple:
# build it
mvn package

# run your program and print the table of methods sorted by their sample count
# and the flame graph, taking a sample every 10ms
java -javaagent:target/tiny-profiler.jar=flamegraph=flame.html ...
You can easily run it on the renaissance benchmark and create the flame graph shown earlier:
The overhead for this example is around 2% on my MacBook Pro 13″ for a 10ms interval, which makes the profiler usable when you ignore the safepoint-bias.
Conclusion
Writing a Java profiler in 240 lines of pure Java is possible and the resulting profiler could even be used to analyze performance problems. This profiler is not designed to replace real profilers like async-profiler, but it demystifies the inner workings of simple profilers.
I hope you enjoyed this code-heavy blog post. As always I’m happy for any feedback, issue, or PR. Come back next week for my next blog post on profiling.
This blog post is part of my work in the SapMachine team at SAP, making profiling easier for everyone.Significant parts of this post have been written below the English channel…
In my last post, I covered a correctness bug in the fundamental Java profiling API AsyncGetCallTrace that I found just by chance. Now the question is: Could we find such bugs automatically? Potentially uncovering more bugs or being more confident in the absence of errors. I already wrote code to test the stability of the profiling APIs, testing for the absence of fatal errors, in my jdk-profiling-tester project. Such tools are invaluable when modifying the API implementation or adding a new API. This post will cover a new prototypical tool called trace_validation and its foundational concepts. I focus here on the AsyncGetCallTrace and GetStackTrace API, but due to the similarity in the code, JFR should have similar correctness properties.
The tool took far longer to bring to a usable(ish) state, this is why I didn’t write a blog post last week. I hope to be on schedule again next week.
AsyncGetCallTrace and GetStackTrace
A short recap from my blog series “Writing a Profiler from Scratch”: Both APIs return the stack trace for a given thread at a given point in time (A called B, which in turn called C, …):
AsyncGetCallTrace
The only difference is that AsyncGetCallTrace (ASGCT) returns the stack trace at any point in the execution of the program and GetStackTrace (GST) only at specific safe points, where the state of the JVM is defined. GetStackTrace is the only official API to obtain stack traces but has precision problems. Both don’t have more than a few basic tests in the OpenJDK.
Correctness
But when is the result of a profiling API deemed to be correct? If it matches the execution of the program.
This is hard to check if we don’t modify the JVM itself in general. But it is relatively simple to check for small test cases, where the most run-time is spent in a single method. We can then just check directly in the source code whether the stack trace makes sense. We come back to this answer soon.
The basic idea for automation is to compare the returns of the profiling API automatically to the returns of an oracle. But we sadly don’t have an oracle for the asynchronous AsyncGetCallTrace yet, but we can create one by weakening our correctness definition and building up our oracle in multiple stages.
Weakening the correctness definition
In practice, we don’t need the profiling APIs to return the correct result in 100% of all cases and for all frames in the trace. Typical profilers are sampling profilers and therefore approximate the result anyway. This makes the correctness definition easier to test, as it let’s us make the trade-off between feasibility and precision.
Layered oracle
The idea is now to build our oracle in different layers. Starting with basic assumptions and writing tests to verify that the layer above is probably correct too. Leading us to our combined test of asynchronous AsyncGetCallTrace. This has the advantage that every check is relatively simple, which is important, because the whole oracle depends on how much we trust the basic assumptions and the tests that verify that a layer is correct. I describe the layers and checks in the following:
Different layers of trace_validation
Ground layer
We start with the most basic assumption as our ground layer: An approximation of the stack traces can be obtained by instrumenting the byte code at runtime. The idea is to push at every entry of a method the method and its class (the frame) onto a stack and to pop it at every exit:
class A {
 void methodB() {
   // ...
 }
}
Is transformed into:
class A {
 void methodB() {
   trace.push("A", "methodB");
   // ...
   trace.pop();
 }
}
The instrumentation agent modifies the bytecode at runtime, so every exit of the method is recorded. I used the great Javassist library for the heavy lifting. We record all of this information in thread-local stacks.
This does not capture all methods, because we cannot modify native methods which are implemented in C++, but it covers most of the methods. This is what I meant by an approximation before. A problem with this is the cost of the instrumentation. We can make a trade-off between precision and usefulness by only instrumenting a portion of methods.
We can ask the stack data structure for an approximation of the current stack trace in the middle of every method. These traces are by construction correct, especially when we implement the stack data structure in native code, only exposing the Trace::push and Trace::pop methods. This limits the code reordering by the JVM.
GetStackTrace layer
This API is, as I described above, the official API to get the stack traces and it is not limited to basic stack walking, as it walks only when the JVM state is defined. One could therefore assume that it returns the correct frames. This is what I did in my previous blog post. But we should test this assumption: We can create a native Trace::check which calls GetStackTrace and checks that all frames from Trace are present and in the correct order. Calls to this method are inserted after the call to Trace::push at the beginning of methods.
There are usually more frames present in the return of GetStackTrace, but it is safe to assume that the correctness attributes approximately hold true for the whole GetStackTrace too. One could of course check the correctness of GetStackTrace at different parts of the methods. I think that this is probably unnecessary, as common Java programs call methods every few bytecode instructions.
This layer gives us now the ability to get the frames consisting of method id and location at safe points.
Safe point AsyncGetCallTrace layer
We can now use the previous layer and the fact that the result of both APIs has almost the same format, to check that AsyncGetCallTrace returns the correct result at safe points. Both APIs should yield the same results there. The check here is as simple as calling both APIs in the Trace::check method and comparing their results (omitting the location info as this is less stable). This has of course the same caveats as in the previous layer, but this is acceptable in my opinion.
If you’re curious: The main difference between the frames of both APIs is the magic number that ASGCT and GST use to denote native methods in the location field.
Async AsyncGetCallTrace layer
Our goal is to convince ourselves that AsyncGetCallTrace is safe at non safepoints under the assumption that AsyncGetCallTrace is safe at safe points (here the beginning of methods). The solution consists of two parts: The trace stack which contains the current stack trace and the sample loop which calls AsyncGetCallTrace asynchronously and compares the returns with the trace stack.
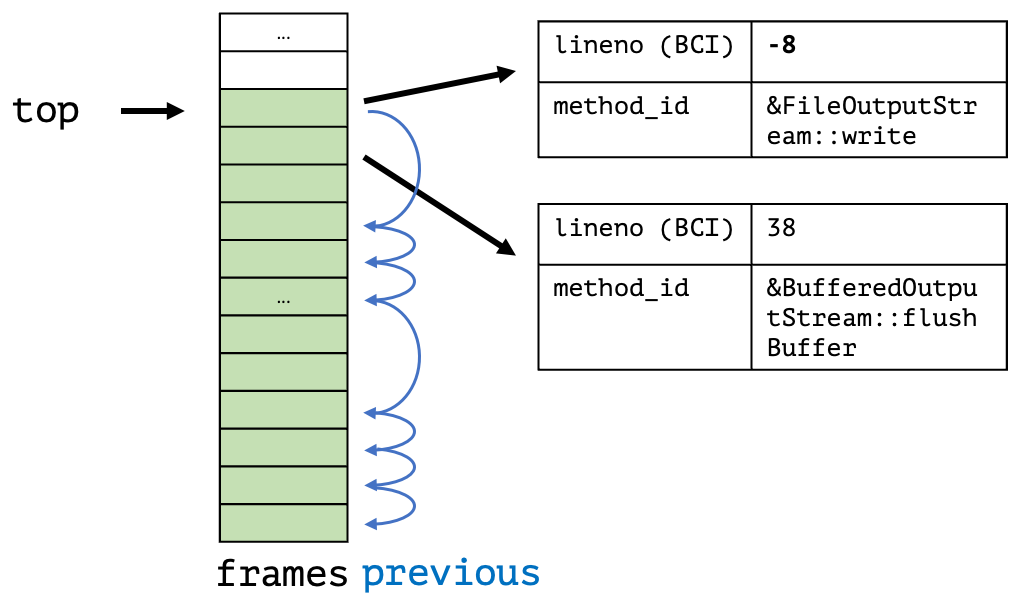
The trace stack datastructure allows to push and pop stack traces on method entry and exit. It consists of a large frames array which contains the current frames: index 0 has the bottom frame and index top contains the top most frame (the reverse order compared to AsyncGetCallTrace). The array is large enough, here 1024 entries, to be able to store stack traces of all relevant sizes. It is augmented by a previous array which contains the index of the top frame of most recent transitive caller frame of the current top frame.
Trace stack data structure used to store the stack of stack traces
We assume here that the caller trace is a sub trace of the current trace, with only the caller frame differing in the location (lineno here). This is due to the caller frame location being the beginning of the method where we obtained the trace. The calls to other methods have different locations. We mark the top frame location therefore with a magic number to state that this information changes during the execution of the method.
This allows us to store the stack of stack traces in a compact manner. We create such a data structure per thread in thread local storage. This allows us to obtain a possibly full sub trace at every point of the execution, with only the top frame location of the sub trace differing. We can use this to check the correctness of AsyncGetCallTrace at arbitrary points in time:
We create a loop in a separate thread which sends a signal to a randomly chosen running Java thread and use the signal handler to call AsyncGetCallTrace for the Java thread and to obtain a copy of the current trace stack. We then check that the result is as expected. Be aware of the synchronization.
With this we can be reasonably certain that AsyncGetCallTrace is correct enough, when all layer tests run successfully on a representative benchmark like renaissance. An prototypical implementation of all of this is my trace_validation project: It runs with the current head of the OpenJDK without any problems, except for an error rate of 0.003% percent for the last check (depending on the settings, but also with two caveats: the last check still has the problem of sometimes hanging, but I’ll hope to fix it in the next few weeks and I only tested it on Linux x86.
There is another possible way to implement the last check which I didn’t implement (yet), but which is still interesting to explore:
Variant of the Async AsyncGetCallTrace check
We can base this layer on top of the GetStackTrace layer too by exploiting the fact that GetStackTrace blocks at non safe points until a safe point is reached and then obtain the stack trace (see JBS). Like with the other variant of the check, we create a sample loop in a separate thread, pick a random Java thread, send it a signal, and then call AsyncGetCallTrace in the signal handler. But directly after sending the signal, we call GetStackTrace, to obtain a stack trace at the next safe point. The stack trace should be roughly the same as the AsyncGetCallTrace trace, as the time delay between their calls is minimal. We can compare both traces and thereby make an approximate check.
The advantage is that we don’t do any instrumentation with this approach and only record the stack traces that we really need. The main disadvantage is that it is more approximate as the time between timing of AsyncGetCallTrace and GetStackTrace is not obvious and certainly implementation and load specific. I did not yet test it, but might do so in the future because the setup should be simple enough to add it to the OpenJDK as a test case.
Update 20th March: I implemented this variant (and it will be soon the basis of a JTREG test) and found an error related to custom class loaders.
Update 21st March: I implemented the reduced version in a stand-alone agent that can be found on GitHub.
Conclusion
I’ve shown you in this article how we can test the correctness of AsyncGetCallTrace automatically using a multi level oracle. The implementation differs slightly and is more complicated then expected, because of the percularities of writing an instrumentation agent with a native agent and a native library.
I’m now fairly certain that AsyncGetCallTrace is correct enough and hope you’re too. Please try out the underlying project and come forward with any issues or suggestions.
This blog post is part of my work in the SapMachine team at SAP, making profiling easier for everyone.
Profilers are great tools in your toolbox, like debuggers, when solving problems with your Java application (I’ve been on a podcast on this topic recently). I’ll tell you some of their problems and a technique to cope with them in this blog post.
There are many open-source profilers, most notably JFR/JMC, and async-profiler, that help you to find and fix performance problems. But they are just software themself, interwoven with a reasonably large project, the OpenJDK (or OpenJ9, for that matter), and thus suffer from the same problems as the typical problems of application they are used to profile:
Tests could be better
Performance and accuracy could be better
Tests could be more plentiful, especially for the underlying API, which could be tested well
Changes in seemingly unrelated parts of the enclosing project can adversely affect them
Therefore you take the profiles generated by profilers with a grain of salt. There are several blog posts and talks covering the accuracy problems of profilers:
I would highly recommend you to read my Writing a profiler from scratch series If you want to know more about how the foundational AsyncGetCallTrace is used in profilers. Just to list a few.
A sample AsyncGetCallTraceTrace bug
A problem that has been less discussed is the lacking test coverage of the underlying APIs. The AsyncGetCallTrace API, used by async-profiler and others, has just one test case in the OpenJDK (as I discussed before). This test case can be boiled down to the following:
import java.lang.reflect.InvocationTargetException;
import java.lang.reflect.Method;

public class Main {

    static { /** load native library */ }

    public static void main(String[] args) throws Exception {
        Class<?> klass = Main.class;
        Method mainMethod = klass.getMethod("test");
        mainMethod.invoke(null);
    }

    public static void test() {
        if (!checkAsyncGetCallTraceCall()) {
            throw ...;
        }
    }

    public static native boolean checkAsyncGetCallTraceCall();
}
This is the simplest test case that can be written in the OpenJDK JTREG test framework for OpenJDK. The problem with this test case? The implementation of checkAsyncGetCallTraceCall only checks for the topmost frame. To test AsyncGetCallTrace correctly here, one should compare the trace returned by this call with the trace of an oracle. We can use GetStackTrace (the safepoint-biased predecessor of ASGCT) here as it seems to return the correct trace.
GetStackTrace returns something like the following:
This problem can be observed with a modified test case with JFR and async-profiler too:
public class Main {

    public static void main(String[] args) throws Exception {
        Class<?> klass = Main.class;
        Method mainMethod = klass.getMethod("test");
        mainMethod.invoke(null);
    }

    public static void test() {
        javaLoop();
    }

    public static void javaLoop() {
        long start = System.currentTimeMillis();
        while (start + 3000 > System.currentTimeMillis());
    }
}
The expected flame graph is on the left (obtained after fixing the bug), and the actual flame graph is on the right.
So the only test case on AsyncGetCallTrace in the OpenJDK did not properly test the whole trace. This was not a problem when the test case was written. One can expect that its author checked the entire stack trace manually once and then created a small check test case to test the first frame, which is not implementation specific. But this is a problem for regression testing:
The Implementation of JEP 416: Reimplement Core Reflection with Method Handle in JDK 18+23 in mid-2021 modified the inner workings of reflection and triggered this bug. The lack of proper regression tests meant the bug had only been discovered a week ago. The actual cause of the bug is more complicated and related to a broken invariant regarding stack pointers in the stack walking. You can read more on this in the comments by Jorn Vernee and Richard Reingruber to my PR.
My PR improves the test by checking the result of AsyncGetCallTrace against GetStackTrace, as explained before, and fixing the bug by slightly loosening the invariant.
My main problem with finding this bug is that it shows how the lack of test coverage for the underlying profiling APIs might cause problems even for profiling simple Java code. I only found the bug because I’m writing many tests for my new AsyncGetStackTrace API. It’s hard work, but I’m convinced this is the only way to create a reliable foundation for profilers.
Profilers in a loop
Profilers have many problems but are still helpful if you know what they can and cannot do. They should be used with care, without trusting everything they tell you. Profilers are only as good as the person interpreting the profiler results and the person’s technique.
I have a background in computer science, and every semester I give students in a paper writing lab an hour-long lecture on doing experiments. I started this a few years back and continue to do it pro-bono because it is an important skill to teach. One of the most important things that I teach the students is that doing experiments is essentially a loop:
You start with an abstract model of the experiment and its environment (like the tool or algorithm you’re testing). Then you formulate a hypothesis in this model (e.g., “Algorithm X is faster as Y because of Z”). You might find problems in your model during this step and go back to the modeling step, or you don’t and start evaluating, checking whether the hypothesis holds. During this evaluation, you might find problems with your hypothesis (e.g., it isn’t valid) or even your model and go back to the respective step. Besides problems, you usually find new information that lets you refine your model and hypothesis. Evaluating without a mental model or a hypothesis makes it impossible to interpret the evaluation results correctly. But remember that a mismatch between hypothesis and evaluation might also be due to a broken evaluation.
The same loop can be applied to profiling: Before investigating any issue with a program, you should acquire at least a rough mental model of the code. This means understanding the basic architecture, performance-critical components, and the issues of the underlying libraries. Then you formulate a hypothesis based on the problem you’re investigating embedded in your mental model (e.g., “Task X is slow because Y is probably slow …”). You can then evaluate the hypothesis using actual tests and a profiler. But as before, remember that your evaluation might also contain bugs. You can only discover these with a mental model and a reasonably refined hypothesis.
This technique lets you use profilers without fearing that spurious errors will lead you to wrong conclusions.
I hope you found this article helpful and educational. It is an ongoing effort to add proper tests and educate users of profilers. See you in the next post when I cover the next step in writing a profiler from scratch.
This blog post is part of my work in the SapMachine team at SAP, making profiling easier for everyone.
Did you ever wonder whether JFR timestamps use the same time source as System.nanoTime? This is important when you have miscellaneous logging besides JFR events; otherwise, you could not match JFR events and your logging properly. We assume here that you use System.nanoTime and not less-suited timing information from System.currentTimeMillis.
The journey into this started with a question on the JDK Mission Control slack channel, which led me into a rabbit hole:
Could I have a question regarding JFR timestamps? (working with Linux) Is there any difference between JFR timestamp implementation and System#nanoTime (any optimization)?
Petr Bouda
This question essentially boils down to comparing both methods’ OS time sources. We’re only considering Unix systems in the following.
Source of JFR timestamps
The JFR event time stamps are set in the JFR event constructor, which is defined in jfrEvent.hpp (and not in the Java code, as one might expect):
The RDTSC instruction reads the time stamp counter on x86 processors:
The time stamp counter (TSC) is a hardware counter found in all contemporary x86 processors. The counter is implemented as a 64-bit model-specific register (MSR) that is incremented at every clock cycle. The RDTSC (“read time stamp counter”) register has been present since the original Pentium.
Already because of the access method, TSC provides a low-overhead and high-resolution way to obtain CPU timing information. This traditional premise was violated when such factors as system sleep states, CPU “hotplugging”, “hibernation”, and CPU frequency scaling were introduced to the x86 lineage. This was however mainly a short abruption: in many new x86 CPUs the time stamp counter is again invariant with respect to the stability of the clock frequency. Care should be however taken in implementations that rely on this assumption.
Returns current value of a clock that increments monotonically in tick units (starting at an arbitrary point), this clock does not increment while the system is asleep.
Information on the implementation of this method is scarce, but source code from 2007 suggests that mach_absolute_time is RDTSC based. So there is (probably) no difference between JFR timestamps and System.nanoTime on Mac OS, regardless of the CPU architecture.
Now on Linux: Here, the used os::javaTimeNanosis implemented using clock_gettime(CLOCK_MONOTONIC, ...):
CLOCK_MONOTONIC Clock that cannot be set and represents monotonic time since some unspecified starting point.
I tried to find something in the Linux Kernel sources, but they are slightly too complicated to find the solution quickly, so I had to look elsewhere. Someone asked a question on clock_gettime on StackOverflow. The answers essentially answer our question too: clock_gettime(CLOCK_MONOTONIC, ...) seems to use RDTSC.
Conclusion
JFR timestamps and System.nanoTime seem to use the same time source on all Unix systems on all platforms, as far as I understand it.
You can stop the JVM from using RDTSC by using the -XX:+UnlockExperimentalVMOptions -XX:-UseFastUnorderedTimeStamps JVM flags (thanks to Richard Startin for pointing this out). You can read Markus Grönlunds Mail on Timing Differences Between JFR and GC Logs for another take on JFR timestamps (or skip ahead):
JFR performance as it relates to event generation, which is also functional for JFR, reduce to a large extent to how quickly a timestamp can be acquired. Since everything in JFR is an event, and an event will have at least one timestamp, and two timestamps for events that represent durations, the event generation leans heavily on the clock source. Clock access latencies is therefore of central importance for JFR, maybe even more so than correctness. And historically, operating systems have varied quite a bit when it comes to access latency and resolution for the performance timers they expose.
What you see in your example is that os::elapsed_counter() (which on Windows maps to QueryPerformanceCounter() with a JVM relative epoch offset) and the rdtsc() counter are disjoint epochs, and they are treated as such in Hotspot. Therefore, attempting to compare the raw counter values is not semantically valid.
Relying on and using rdtsc() come with disclaimers and problems and is generally not recommended. Apart from the historical and performance related aspects already detailed, here is a short description of how it is treated in JFR:
JFR will only attempt to use this source if it has the InvariantTSC property, with timestamp values only treated relative to some other, more stable, clock source. Each “chunk” (file) in JFR reifies a relative epoch, with the chunk start time anchored to a stable timestamp (on Windows this is UTC nanoseconds). rdtsc() timestamps for events generated during that epoch are only treated relative to this start time during post-processing, which gives very high resolution to JFR events. As JFR runs, new “chunks”, and therefore new time epochs, are constructed, continuously, each anchored anew to a stable timestamp.
The nature of rdtsc() querying different cores / sockets with no guarantee of them having been synchronized is of course a problem using this mechanism. However, over the years, possible skews have proven not as problematic as one might think in JFR. In general, the relative relations between the recorded JFR events give enough information to understand a situation and to solve a problem. Of course, there are exceptions, for example, when analyzing low-level aspects expecting high accuracy, usually involving some correlation to some other non-JFR related component. For these situations, an alternative is to turn off rdtsc() usages in JFR using the flags: -XX:+UnlockExperimentalVMOptions -XX:-UseFastUnorderedTimeStamps. JFR will now use os::elapsed_counter() as the time source. This comes with higher overhead, but if this overhead is not deemed problematic in an environment, then this is of course a better solution.
As other have already pointed out, there have been evolution in recent years in how operating systems provide performance counter information to user mode. It might very well be that now the access latencies are within acceptable overhead, combined with high timer resolution. If that is the case, the rdtsc() usages should be phased out due to its inherent problems. This requires a systematic investigation and some policy on how to handle older HW/SW combinations – if there needs to be a fallback to continue to use rdtsc(), it follows it is not feasible to phase it out completely.
Difference between System.currentTimeMillis and System.nanoTime
This is not directly related to the original question, but nonetheless interesting. System.currentTimeMillis is implemented using clock_gettime(CLOCK_REALTIME, ...) on all CPU architectures:
CLOCK_REALTIME System-wide realtime clock. Setting this clock requires appropriate privileges.
CLOCK_REALTIME represents the machine’s best-guess as to the current wall-clock, time-of-day time. […] this means that CLOCK_REALTIME can jump forwards and backwards as the system time-of-day clock is changed, including by NTP.
CLOCK_MONOTONIC represents the absolute elapsed wall-clock time since some arbitrary, fixed point in the past. It isn’t affected by changes in the system time-of-day clock.
So does it make a difference? Probably only slightly, especially if you’re running shorter profiling runs. For longer runs, consider using System.nanoTime.
I hope you enjoyed coming down this rabbit hole with me and learned something about JFR internals along the way.
This blog post is part of my work in the SapMachine team at SAP, making profiling easier for everyone.
Es ist lange her, dass ich das letzte Mal in diesem Blog einen Beitrag geschrieben. Deswegen kommen in der nächsten Beiträge über Dinge die liegen geblieben sind.
Anfang 2016 beendete ich das schreiben an meiner Bachelorarbeit mit dem Titel “Besser Benchmarken” in deren Rahmen ich das Benchmarkingwerkzeug temci entwickelte.
Es ging in der Bachelorarbeit darum, dass die Anfertigung korrekter Benchmarks recht schwierig ist und deswegen ein Werkzeug zur Vereinfachung nötig ist. Solch ein Werkzeug ist temci, es erlaubt das einfache Erstellen von Benchmarks und eine einfache statistische Auswertung.
Außerdem ging es in der Arbeit um die (theoretischen) Grundlagen für gute Benchmarks. Diese Grundlagen habe ich dann auch in einem Vortrag auf der GPN 2016 vorgetragen:
Update: This post (and the bug report Joachim Breitner submitted in succession) resulted in the change of the haskell documentation: The statement “At the moment, -O2 is unlikely to produce better code than” was removed from the documentation two months after this post. A denser and cleaner representation of the data and the main arguments is given in my bachelor thesis (written in german) that I finished around the same time.
TL;DR: There’s no significant difference between the GHC versions 7.* and 8.0.1-alpha regarding the Haskell code used in the benchmarking game. And there might be an improvement of the performance of idiomatic Haskell code from GHC 7.0.1 to GHC 8.0.1-alpha.
I’m currently building a new benchmarking tool called temci as part of my bachelor thesis.
In search for good programs to benchmark for the evaluation part, I stumbled across the benchmarking game. This blog posts is about using parts of the benchmarking game and temci to measure and compare the performance of the following GHC versions: 7.0.1, 7.2.1, 7.4.1, 7.6.1, 7.8.1, 7.10.1 and 8.0.0 (the version from mid January, called 8.0.1 here for brevity) using different optimization levels (“-O”, “-O2” and “-Odph”, see: Haskell documentation) . Continue reading →
Any regular language L has a magic number p
And any long-enough word in L has the following property:
Amongst its first p symbols is a segment you can find
Whose repetition or omission leaves x amongst its kind.
So if you find a language L which fails this acid test,
And some long word you pump becomes distinct from all the rest,
By contradiction you have shown that language L is not
A regular guy, resiliant to the damage you have wrought.
But if, upon the other hand, x stays within its L,
Then either L is regular, or else you chose not well.
For w is xyz, and y cannot be null,
And y must come before p symbols have been read in full.
As mathematical postscript, an addendum to the wise:
The basic proof we outlined here does certainly generalize.
So there is a pumping lemma for all languages context-free,
Although we do not have the same for those that are r.e.
There are some other poems by Harry Mairson at http://www.cs.brandeis.edu/~mairson/poems/poems.html. I found this poem while reading a discussion at The Old Joel on Software Forum.
I currently have a course covering operating systems at university. We learn in this course several scheduling algorithms. An operating system needs these kind of algorithms to determine which process to run at which time to allow these process to be executed “simultaniously” (from the users view).
Good scheduling algorithms have normally some very nice features:
They avoid the starving of one process (that one process can’t run at all and therefore makes no progress).
That all processes run the approriate percentage (defined by it’s priority) of time in each bigger time interval.
But they are maybe not only useful for operating systems but also for people like me. Probably they could help me to improve the scheduling of my learning.
An algorithm that seems to be suited best for this purpose is called lottery scheduling (pdf). It’s an algorithm that gives a each process some lottery tickets (their number resembles the priority of the process). Every time the algorithm has to choose a new process to run, it simply picks a lottery ticket randomly and returns the process that owns the ticket. A useful addition is (in scenarios with only a few tickets) to remove the tickets that are picked temporarily from the lottery pot and put them back again, when the pot is empty.
But how could I use this algorithm in practice?
I take a stack of blanko cards, each card worth around 2 hours of learning time, and assign them to each of my courses. E.g. the course operating systems gets 3 cards, out of the 25 cards that now make up my week.
Now, when I’ve time to learn, I pick a card out of the shuffeled card stack which then tells me to learn about 2 hours e.g. for my theoretical computer science course.
This “practical exercise” in operating systems will hopefully boost my learning – and of course is funny way to learn, as I never know what I’m going to learn. Later, I probably also could use it to ensure that I’m blogging more regularly here and progress with my compiler project.
The POOL programming language is a cool project – it’s fun to write your own programming language that does everything the way you like. I’ll give a short status update for this project in this article, as I’m going to delay it.
The problem with this project and the reason why I delay it (maybe some month or years) is that I realized that I lack the knowledge of creating and implementing programming languages. I’ve never developed a real Turing complete programming language before, but writing the real POOL implementation is such a hugh project that it’s probably better that I gained experience in this field before attempting it again. It’s a pity that I can’t implement it within the next couple of months as I developed POOL in my mind for about half a year.
What I currently have programmed for the POOL project are two failing attempts to write a grammar and a rough draft of a byte code interpreter (aka virtual machine). I’ve spend dozens of days for this attempts and drafts – but there are no real results. And that’s the real reason why I delay this project: I’m working hours and hours without any substantial progress – that’s really demotivating – and the probability that this project therefore fails after hundreds of hours of developing is high.
But what am I going to do next? I’m addicted to writing compilers, parsers and interpreters for unknown languages, but instead of starting another huge project like POOL, I’m going to start many little projects that don’t last that long.
One of this project’s is OrangeLang a cool project about a minimal language with focus on the complier. I’ll post an article on this blog when the project has more than a rugh compiler draft. (That has been also a difficulty with POOL: I wrote several articles and talked with people about it without having anything to show)
The following is a short and drafted schedule for the POOL project, it doesn’t contain any dates and should only give an idea, what I’m going to do next in the project and what I’ve already done.
Almost done
Create a draft of the syntax (I’ve to admit that I’m currently working on the class syntax and on the variable container syntax)
TODO
Publish the draft
Figure out the core libraries (like System, etc.)
Parser grammar, which produces the AST
Tree filters to optimize and annotate the AST (convert for example 2+3 to 5)
Tree based interpreter
Objects, scope, functions, etc.
Tree based interpretation
Optimization of the interpreter
More built in libraries
Language manual with lot’s of example code and a website as I think the project will (after creating a tree based interpreter) more than half a year old.
This article is an collection of my thoughts on the syntax of the POOL programming language. It may evolve and be updated (and written) over time. Furthermore it’s like a blue print for my later work on the parser and the grammar, therefore it’s written like a language reference. It’s my first article of this kind (and its using terms from Java, JavaScript and Ruby), but I hope it’s none the less readable and gives a good (and deep) overview of the language.
Notes on the formatting of this article
Uppercased words or words in brackets are placeholder.
CODE #-> VALUE means that the CODE returns (or emmits) VALUE
CODE #~> VALUE means that the CODE returns (or emmits) something equivalent to VALUE
, ... means that the pattern used before the comma is repeated
Syntax basis and philosophy
The syntax of the language is heavily based on the syntax of JavaScript (JavaScript is even to some extend valid pool code) and Ruby as JavaScript has an easy syntax and I like Ruby (it’s syntax is great and easy to understand). Therefore the syntax for simple comments, assignments, property access, method calls and primitive data types (I mean numbers, arrays, strings and booleans) is the same as in JavaScript (and Ruby) and so I assume that you understand this parts of the syntax when used here, I set it for now at side and cover them after core parts of the syntax later.
The philosophy of this syntax to emphasize that everything (yes, everthing) is an object and to allow as much flexibility as possible.
Objects
Objects are the base of the language, so their syntax one is really simple (an bourroughed from JavaScript): obj = {"KEY": [value or expression], ...}, if KEY is a valid variable name or not a string obj = {KEY: [value or expression], ...} or an empty object empty_object = {}.
Elements of the object can be accessed either with obj["KEY"] or if KEY is a valid variable name obj.KEY. Not existing properties have the value nil, if a not existing method is called on this object, it’s undefined_method function is called (as you may have recognized, I use the term method and the term function mostly as synonyms). Inside the object, you can directly access its properties with just KEY if KEY is a valid variable name (but later more on this topic).
Every object has some properties and methods built in (which can be overriden, but be really careful), some of them have aliases for convenience:
$size
the number of key value pairs in the object minus the built in ones (and the ones beginning with $.
function $contains(KEY)
checks whether the object contains the KEY
function $delete(KEY)
deletes the KEY value pair
this or $this
the current object
$parent
the object this object is a part of – the parent object. @KEY is a short cut for $parent.KEY
$module
the module this object is part of ($module and $parent could possibly be the same)
$type or $class
type of the object: obj.$type == "Object": the object is a simple objectobj.$type == "Module": the object is a moduleobj.$type == "Function": the object is a functionelse the class name of object, alias for $class.name
$class
Class object this object is an instantiation of.
Normal object: Object, …
Class object: Object
function undefined_method([method name], [parameter object])
This method is called whenever a not existing method is called on this object (e.g. obj.not_existing_method(34)). The default implementation throws an exception.
$private
An object containing the private properties of this object.
$protected
An object containing the private properties of this object which are also accesible from subclasses (is only important in class definitions)
$module_private
An object containing the properties accesible from within the same module.
The object inherits some more built in methods and properties which will be described in a detailed object reference.
Modules
Modules are simply objects with a different syntax, the ability to import functions and objects of another module in to it via the built in import([module reference or module name]) function (if there is no such module, the interpreter searches and requires the appropiate file if their is one, if not throws an error). The code inside a module is excecuted when it’s loaded or required (via function require("FILE_NAME"), if FILE_NAME has no file ending, the function adds .pool). Modules can be nested in side one another, but not into objects.
Their syntax is easy:
module MODULE_NAME {
[CODE]
}
or in a more literal and Ruby like style:
module MODULE_NAME

[CODE]

end
Example:
module Test.Module //Every valid reference is alowed. Just Test has to be a module (it will be created if is doesn't exist)

import(IO) //IO is a built in module

obj = {"3": 3} //creates an object, that can be accessed from the outside via Test.Module.obj

end
Every code outside a module (and modules outside of other modules) are placed into the STDModule.
As Modules are (after they’re loaded) some kind of objects they inherit the built in functions and properties of them.
Functions
Define a function:
function [variable name]([parameter list]){

[CODE]

}
Define a closure:
[variable name] = function([parameter list]){

[CODE]

}
Or in a shorter way
[variable name] = {|[parameter list]|

[CODE]

}
or (of course)
[variable name] = do |[parameter list]|

[Code]

end
|| can be omited if the closure has no parameters.
Closure and functions are over all the same, in fact the only difference between the two is, that functions allow back referencing (the interpreter recognizes them during parsing). Therefore function can be used as closures and so everything I say about functions will (if I say nothing explicit) also apply to closures.
The parameter list: [parameter (a normal variable name, the given value is assigned to)], [another parameter], ...
Or if you want to set a default value for one parameter: [parameter]: [default value], ...
If you use an expression instead of an explicit value, the value will be evaluated every time the default value is used. But if you put a ~ in front of the colon (~:) the value will only be evaluated once and then cached (so don’t use $caller there). It’s also important, that the scope of such an expression is the function scope (you’re able to use $caller, $this, …).
If you want to auto clone the given value of a parameter (I know, it’s the other way aorund in PHP but hopefully it’s not to hard to memoize the difference) you can prefix PARAMETER with an ampersand (&PARAMETER).
You’re able to preset a return value for a given set of parameters of a function:
FUNCTION(3) = 4
Built in variables of of the function object:
this or $this
the current function object
$this.$caller or simply $caller
the caller function object
$local
the local variables
$param
the current parameter object, $param = {[first parameter name]: [value], ..., $other = []}.
If a parameter isn’t given, it’s value is nil, if a parameter is given without a corresponding parameter name, it’s added to the $other array Please don’t use constructs like the caller of the parent object, as it’s value is going to be nil and therefore is useless.
$default
the parameter default values, $default = {[first parameter with default value]: [default value], ...}
$ast:
it will probably be added later and will allow the modification of the Abstract Syntax Tree of the function body.
$yield
Closure the function is called with. Short for $param.$yield
Instead you only using the keywords function or def you’re also able to create special function types by pefixing these words, [prefix]function or [prefix]function (they can also be combined). Special types and their prefixes are the following:
sef_
sef stands for “side effect free”. This function type caches the results in $cache = {[parameter object]: [function result], ...} (could be changed in the future)
pdf_
pdf stands for “preset default value”. It’s a function type that returns the same function with the given parameters preset (their default values, to be correct), if other parameters (with no default values) aren’t set.
They’re simply short cuts for setting the value of the property $is_pdf or $is_sef to true accordingly.
Example:
pdf_function pow(base, exponent) { base ** exponent }

pow_two = pow(exponent: 2) #-> {|base, exponent: 2| base ** exponent}

pow_two(3) #-> 9
Return values
Values are returned explicit via return VALUE or implicit (the value of the last expression is returned).
Call a function
You call a function as you would expect via FUNCTION([first parameter], [second], ...). You’re able to replace [first parameter] with [parameter name]: [parameter value] to set the value of a special parameter out of the normal order (e.g. FUNCTION([first parameter], [parameter name]: [value], [second parameter])). To pass a nil value for a parameter, you can either type nil directly, or omit the value (e.g. FUNCTION([first parameter],, [third parameter]), FUNCTION([first parameter], [parameter name]:, [third parameter])). A nil value is replaced by the default value of the parameter (if there’s one).
You can optionally pass an code block stored in the $yield variable in the function:
FUNCTION(PARAMETERS) CLOSURE

arr.search() {|a, b| a > b }
Variable names
Valid variable (and function and module) names consist of an alphabetical or _ character or a dollar sign optionally followed by alpha numerical or _ characters and optionally ended by a ? or ! character (or as an regular expression /$?[a-zA-Z][a-zA-Z0-9_][!?]?/).
Variable names are case sensitive and only allow ASCII characters (no UFT8).
The following are some naming conventions (partly coming from Ruby, JavaScript and Java and not enforced by the interpreter):
– functions returning booleans end with a ?
– only functions that modify the object, they’re called on, and with a !
– built in functions and properties of objects, functions, etc. start with a $, some have aliases for convenience that aren’t (e.g. $this has the alias this).
– class and module names are camel cased, the other variable names not (using _ instead)
Comments
As I said at the beginning of this article, you’re able to write comments as you’re used to in JavaScript or Ruby, both syntaxes are supported:
One line comment: //COMMENT TEXT or #COMMENT TEXT
Multi line comment:
/*

MULTILINE

COMMENT

*/
or
MULTILINE
COMMENT
Documentating of modules, classes and functions
Documentation consists of multi line comments in front of and is modeled after JavaDoc.
Structure of the comment text:
SHORT DESCRIPTION
OPTIONAL DETAILED DESCRIPTION
OPTIONAL INFORMATION
(the second free line is optional)
Optional information tags (have to be in different lines):
– @version VERSION:
version of the class or etc.
– @license LICENCE
License the code is licensed under.
– @author AUTHOR
Author of the code
Function specific tags:
– @param PARAMETER_NAME TYPE DESCRIPTION
information for the parameter PARAMETER_NAME, if you want to write more than one type, just seperate the types by | characters (e.g. TYPE1|TYPE2.
- @returns TYPE description
information about the return type of the function
Variable assignment = (in object definitions : is used instead but it works similar) without a prefix is asimple assignment by reference. The allowed prefixes are the following:
– ~: lazy assignment
the expression at the right side is evaluated the first time the value of variable is really used
– &: assignment by value
assigns the cloned value of the right side expression to variable
– :: final assignment. (set is_final of the variable object to true)
- ?: sets the value of the variable if it's current value is nil or null, can't be used to assign a value to a set of parameters of a function.
Assignements can be cascaded via commas: [assignment], [assignment]
Variables
:VAR : variable object containing the value of VAR
properties:
set : called when the value of the variable is set
get : called when the variable is accessed
is_final : true if constant
value : value of the variable
Class
class CLASS {new:: function(){}, super: class obj, static: {}, possible: array_get [i], push [<<], pop [>>], add [+], sub [-], mul[*], div [/], mod [%], pow [**]}
for usability reasons some of the magic is performed by the interpreter indirectly, to allow a simpler method definition. I can’t write much about that, as it depends strongly on the implementation. New objects are created via CLASS.new(PARAMTER)
TODO write more text…
Built in types
Built in types are types with a native syntax, like Strings or Numbers
(but without modules, classes, object and functions in this context). The following lists them with their native syntax and a short description.
Float
Syntax to create an floating point number 10: 10.0 or 10f or 1.0E1 or 1fE1 (the number behind E is the exponent x in zEx = (10 ** x) * z) or (of course) Float.new(10)
Integer
The syntax is equivalent to the Float syntax: 10 or 1E1 or Integer.new(10).
If an Integer is used in a expression with a float it will be used as a float. In general float values are rounded to smaller integer if they are converted to an integer.
String
Strings are created via "[characters, can span across lines]" or '[characters]'.
You can insert code into the string (it’s result will be actually inserted) via #{[CODE]} into " Strings (backslash expression like \n are also only converted in this type of String
This code will be treated as a closure: "TEXT #{[CODE]} TEXT"
is equivalent to "TEXT" + {[CODE]}() + "TEXT"
Literal
Essentially Strings consisting of one character, no new class but used in the following as a term.
Boolean
true or TrueClass.new(), false or FalseClass.new().
More information in the section about boolean expressions.
Nil
nil or NilClass.new() acts like false in boolean expressions.
Is the value of an unknown variable or of a function or expression returning no value.
Null
null or NullClass.new() acts like false in boolean expressions.
Is the value of known but unset variables. May be removed later.
Range
BEGIN..END or Range.new(BEGIN, END), BEGIN...END
or Range.new(BEGIN, END, false). Range objects created using ..
run from the beginning to the end inclusively. Those created using ...
exclude the end value. BEGIN and END can be of type Integer, Float or Literal.
RegExp
/[Regular expression]/ or RegExp.new('[Regular expression]').
Is a regular expressions, strings can be matched against.
The actuall regexp syntax is determined during implementation.
Boolean expression
Every value except null, nil and false evaluates to false all other values evaluate to true. There are different types of modifiers in boolean expressions, listed below in their precendence.
EXPR or (EXPR)
The value of the expression, which could also be a single value
!EXPR or not EXPR
Negates the following boolean
EXPR && EXPR or EXPR and EXPR
Logical and.
EXPR || EXPR or EXPR or EXPR
Logical or.
EXPR xor EXPR
Exclusive or.
EXPR == EXPR or (EXPR).equals(EXPR)
True if both values are the same (no automatic casting, therefore no === is needed)
EXPR =~ EXPR
Used when only if one of the to values is an regular expression, the other value is tested against, or if the first value is a range and the second value is included in the range
Control constructs
EXPR is a boolean expression. Variables defined in the code blocks are only visible in this code block, but variables of the sourrounding (module, class, object, function) scope can be accessed without any prefix.
An important information is that such constructs return the value of the last expression of their code and that you can break out such a construct via break (use break DEPT if you want jump out of the DEPTth parent construct), returns the value of the expression before the break.
Conditions
There are several ways to define a simple condition:
if (EXPR){

[CODE]

}
or with only a single of code:
if (EXPR) [single line of code]
or (maybe not implemented)
[single line of code] if (EXPR)
More advanced conditions with if and else:
if (EXPR){

[CODE]

} else {

[CODE]

}
or with only a single of code:
if (EXPR) [single line of code]

else (EXPR) [single line of code]
the same with several conditions:
if (EXPR){

[CODE]

} else if (EXPR) {

[CODE]

} else {

[CODE]

}
You can replace if with unless if you want to execute the code block when the boolean expression is false.
The ternary version is also allowed (as you know it): EXPR ? CODE : CODE .
Switch-case
Switch case statements in POOL are similar to them of other languages like JavaScript, so I'm only going do cover the differences.


switch ([Value or variable, VAL]){

case [EXPR]:

[CODE]

break;

case [EXPR]: [CODE]; break

case~ [EXPR]:

[CODE executed if EXPR =~ VAL is true]

break

case+ [EXPR]:

[CODE executed if EXPR is true]

break

else:

[CODE executed if no other case-condition matches]

}


If switch is replaced with switch+ breaks will be auto inserted after each case statement.
Loops
As you know and love them.
For loop
for ([assign a variable or not]; [condition tested after each loop cycle, or not (then you've got and endless loop)]; [statement executed after every loop cycle]){
[Code]
}
While loop
while(EXPR) {

[CODE]

}
or if you want execute code while the expression is false:
until(EXPR) {

[CODE]

}
Begin-while loop
begin {

[CODE]

} while (EXPR)
or if you want execute code while the expression is false:
begin {

[CODE]

} unless (EXPR)
Infinite loop
loop {

[CODE]

}
Exceptions
The specific exception classes are defined during the implementation. All exception classes extends the class Exception.
Exception throwing
throw [exception class].new([parameters])
Please add a @throws tag to the appropriate comment.
Exception handling
Exceptions are handled with a Java like syntax:
try {

[unsafe code]

} catch ([Exception class, if you catch more than one, seperate them with a vertical bar] [variable the thrown exception is assigned to]) {

[CODE]

}
You can optionally add a finally { [CODE] } after the catch statement, CODE will than be certainly executed and you can add serveral catch statements after the first.
I’m going to post some example code snippets, like the following, written in POOL to demonstrate some of POOLs cool features and to have some test code when I’m writing the parser and the interpreter.
This code snippet eveluates the fibonacci sequence recursively, using the memoizing features of the special function type sef_function to avoid on the usual drawbacks of recursive evaluation: the multiple calculation of the same value.
I’ve a dream to build an object oriented language. Last year, I built an tiny modeling language for Mealy and Moore automatons. It felt great to develop my own little grammar with ANTLR and seeing it working. You can find this project (AutomatonLang) in my github repository. Now as I’m beginning to study computer science, I thought about a new project (after I finished my work for the abipage project) to work on in my spare time, a project that has more to do with my field of study then building little websites, etc. And so some thoughts popped up in my mind. One of it was to realise on of my dreams – to build an programming language. It sounds annoying for most of my contemporaries, but for me it felt just just great thinking about designing and developing a new programming language with grammars, parsers, documentation and everything. It’s now my main spare time project for as long as it takes, I assume several months or more, and I hope it’ll be as much fun as I’m expecting it to be and that I’m learning all sorts of skills (I’m optimistic). I’m going to write, in this and in following blog posts, about thoughts and ideas on programming languages and my attempt to build one on my own. I hope they are helpful to you if you’re planning the same type project. Up to this day I’ve only ideas about the design in my mind and haven’t written any line of code or grammar – this post is about my ideas and the general decisions I’ve made.